AI agent code quality: review generated UI against real docs
AI agents can produce a working screen quickly, then leave a team with a different button, spacing scale, or interaction pattern on every route. The fix is not to ask for a better prompt and hope. Give the agent a codebase it can inspect, documented components it can reuse, and clear instructions about where platform behavior is allowed to differ. Then review the generated diff against the actual package APIs.
That is the practical meaning of AI agent code quality: generated code follows the project’s conventions closely enough that a developer can review, test, and maintain it. A component kit can help by giving the agent existing primitives and documented tokens to build on. It cannot guarantee that an agent will choose the right component, preserve accessibility, or produce identical output on different platforms. Those outcomes still need checks in your repo and app.
Start with the code the agent can actually see
Before asking an agent to build another screen, point it at the source of truth for your project. That might be a CLAUDE.md, Cursor project rules, or another checked-in instruction file. Keep it short enough to stay useful, and cover decisions that affect most tasks:
- Which packages provide the existing UI components and design tokens?
- Where are the relevant component docs and examples?
- Which platform is this screen for?
- What should the agent inspect before editing?
- What checks should it run, and what should it return for review?
A project note might say:
# UI contribution notes

- Read the package documentation for the target platform before using a component.
- Reuse components and tokens already present in this repository.
- Do not assume a web prop exists in the native package, or vice versa.
- Keep platform-specific behavior in the platform implementation.
- Return the changed files and the checks you ran; flag anything you could not verify.
This is an instruction for your project, not a guarantee enforced by the component library. Review the output as code. For Claude Code, the official memory documentation explains how project instructions provide context. Cursor’s rules documentation describes project and other rule scopes. Both are useful places to learn how to keep these instructions near the repo rather than relying on a prompt that disappears after one session.
Shared component names do not mean shared props
Cross-platform libraries often expose familiar names such as Button on more than one platform. That helps a developer find the corresponding concept. It does not mean the implementations have identical props, event handling, accessibility behavior, or rendering.
For example, OTF documents a web Button in @otfdashkit/ui and a native Button in @otfdashkit/ui-native. The web documentation describes solid, outline, ghost, and destructive variants, with icon and loading support. The native documentation describes press-target properties such as variant, size, tone, loading, and disabled. Read the docs for the package you are using and select the props that page documents; do not copy a JSX example from one platform into the other without checking it.
The same distinction applies to design tokens. Shared design tokens can help keep color and spacing decisions aligned. A platform may still need a different interaction or layout to respect its conventions. Aim for a coherent product, not a promise that every screen will look or behave exactly alike.
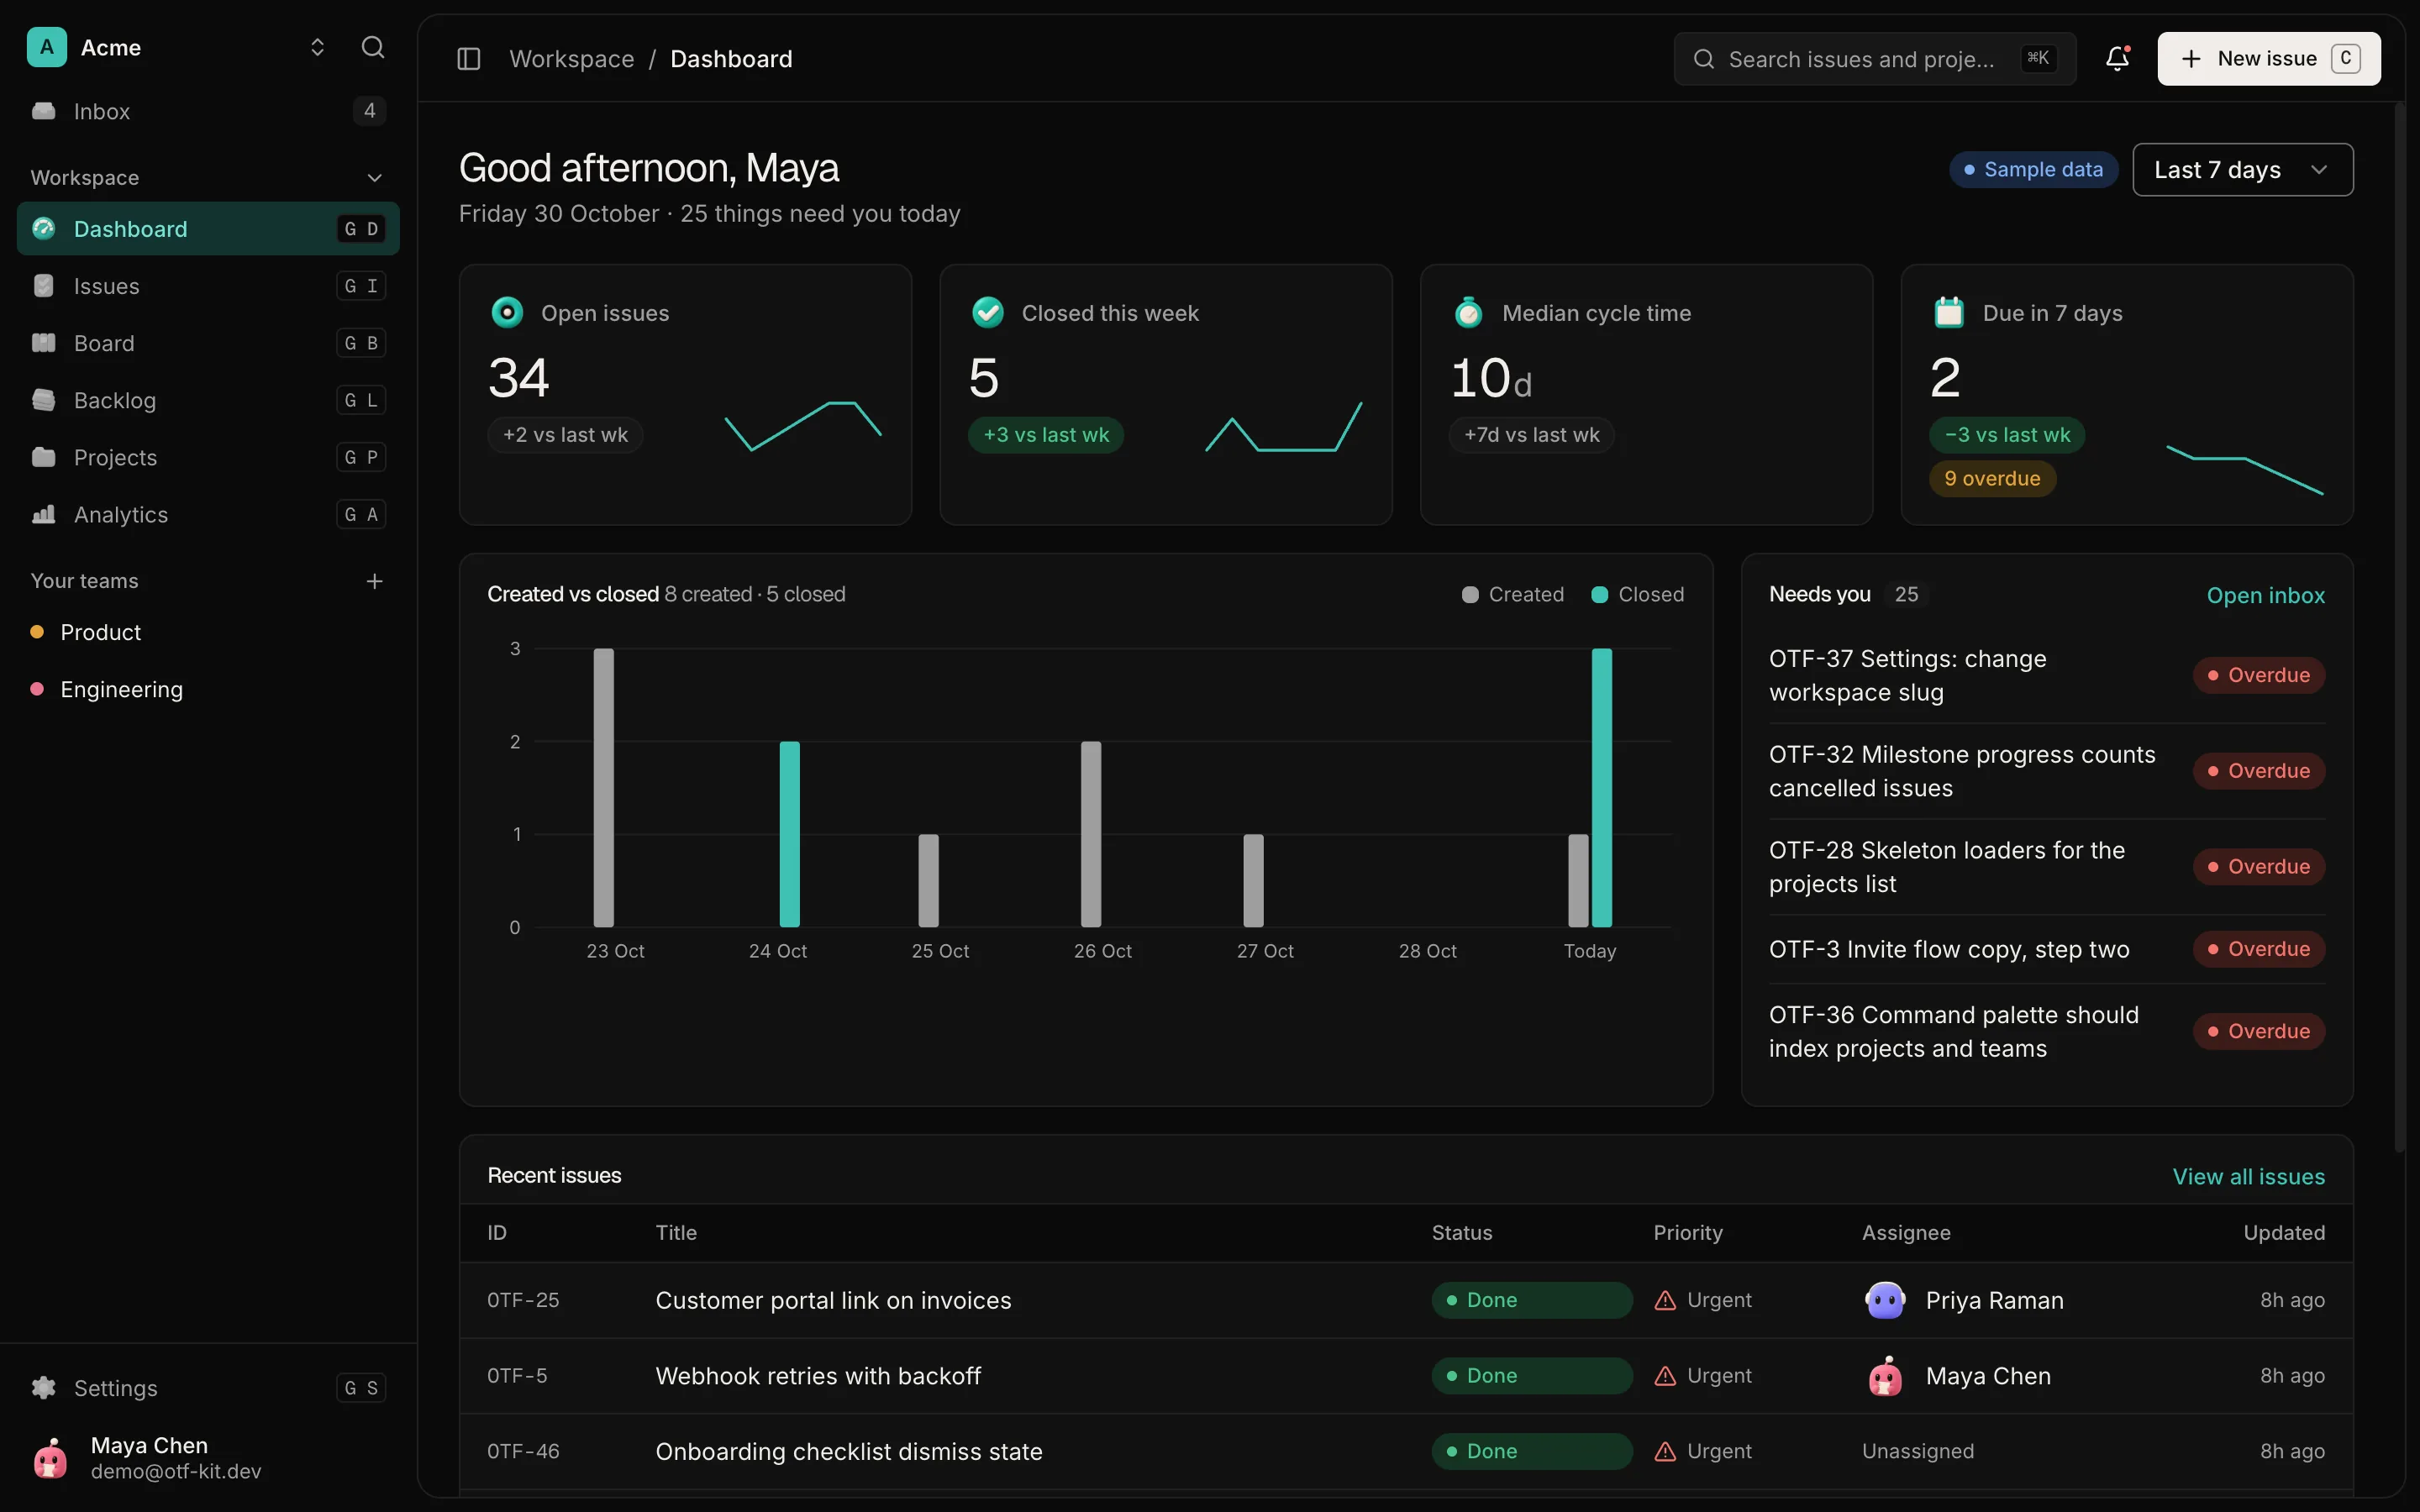
12 production screens. Login and database wired.
The SaaS Dashboard Kit includes login, a database, and a working dashboard. Live demo at saas.otf-kit.dev.
Give the agent a repeatable implementation task
A useful request tells the agent how to discover the existing system and how to show its work. For a pricing screen, for example, ask it to:
- Inspect the package manifests and the current pricing page.
- Find the Button, Card, and token documentation for the screen’s platform.
- Reuse the components that exist; list any missing primitive rather than inventing an undocumented import.
- Make the smallest focused change.
- Run the repository checks that are already configured.
- Return a diff summary, the commands and results, and any assumptions that still need a person’s review.
This workflow makes the result easier to evaluate. It also gives the agent a useful fallback: when the repository does not contain a needed component or the documentation does not answer a question, it should surface that gap instead of fabricating an API.
Do not ask the model to claim tests passed unless it actually ran them. Do not treat a generated screenshot as proof that keyboard navigation, screen-reader output, or touch behavior is correct. Those require the checks appropriate to the platform and the project.
Compose before you add a new primitive
Many product screens are compositions of ordinary pieces: a card, heading, price, feature list, and action. Before accepting a freshly generated component, check whether the repository already has those pieces and whether the target package documents them. If it does, ask the agent to compose them and keep product-specific decisions close to the screen.
If it does not, ask for a proposal that identifies the gap, the platform, the expected API, and the tests needed. A custom component may be the right choice, but it should be reviewed as a new abstraction instead of quietly appearing in one route with hardcoded styles. On web and native, that proposal may lead to separate implementations that share a name or design tokens while retaining platform-specific props.
Review the diff with a short checklist
AI agent code quality is a property of the change you can inspect, not of the agent’s confidence. Before merging a generated UI change, check:
- Imports: Do the components and tokens come from packages that are installed in this app?
- Props: Are the props documented for this platform and package version?
- Scope: Did the agent change only the files needed for the feature?
- Consistency: Does the screen use the repository’s existing component and token choices?
- Behavior: Have you checked the interactions that matter for this screen, including disabled and loading states where applicable?
- Verification: Are the reported type checks, tests, and builds real command results?
- Uncertainty: Did the agent clearly mark missing docs, unsupported APIs, or work it could not verify?
The checklist does not replace your project’s accessibility, visual, or device testing. It helps catch avoidable mismatches before those checks become harder to trace through a large diff.
Put the workflow on a real screen
Try this on one contained feature before changing your whole development process. Choose a screen where an agent has already produced inconsistent components or styling. Add a short project instruction file, link the relevant package docs, and ask the agent to make one small change. Review the imports, props, diff, and actual check output. Record any instruction that prevented a repeat mistake.
For OTF, start with the component catalog, then compare the web Button documentation with the native Button documentation for the platform you are building. If you are evaluating a broader starting point, browse the OTF templates. The related guide on design systems as agent context covers the repository context side of the same workflow.
Sources
- Claude Code — Memory — official documentation for project and other memory scopes.
- Cursor — Rules — official documentation for project and other rule types.
- OTF component catalog — published component catalog.
- OTF web Button — web package Button documentation.
- OTF native Button — native package Button documentation.

Ship the product, not the setup.
- 12 production screens — auth, team, analytics, and settings
- Login and a real database are wired in
- AI configs pre-tuned so your agent extends instead of regenerates
Ship your first screen tonight — free starter in your inbox
The quickstart, the SDK repo and the live kit demos, on this screen and in your inbox.
No spam. Unsubscribe any time.