
How to add script-directed dialogue with a multi-speaker text-to-speech API
A product team can make a single voice read a paragraph in seconds. The harder part is turning a script into a conversation that sounds like two people, follows delivery notes, and still behaves predictably when the app retries or edits a line. If your feature needs character dialogue, narrated scenes, or guided voiceovers, “text-to-speech works” is not enough. You need to decide how scripts, speaker choices, performance direction, and generated audio fit into the product.
Drama 3 is a text-to-speech model from Fish Audio available through Vercel AI Gateway. Vercel’s model page describes natural-language directions for voice performance, including emotion, pacing, pauses, and vocal sounds, and lists multi-speaker dialogue as a use case. It is currently in preview. That makes it worth testing on a real app workflow, but not something to treat as a settled production contract before you verify the current API behavior and terms.
Start with the script, not the model picker
Write a short representative script before building a settings screen. Include at least two speakers, a question and response, one pause, a change in emotion, a proper noun, and a line that should sound different from the default delivery. This will reveal whether the model follows the direction and keeps the voices distinct in the task your users actually care about.
Keep the script as app data instead of burying it in a prompt string. A simple internal shape might include a speaker label, the spoken text, and a delivery note for each turn. Your app can then validate that each turn has text, map a speaker to an approved voice, and preserve the original script when a user asks to regenerate one line. The exact request format for multiple speakers must come from the current model documentation; do not assume the product page’s multi-speaker description means every request accepts arbitrary role markup.
That distinction matters in the UI. A single text box is easy to prototype, but it gives the app little structure for assigning voices or identifying which line needs a correction. A turn-based editor can let a user review the words, choose a speaker, and add a short delivery direction before generation. Keep the first version small: the product is testing a specific workflow, not building a general-purpose audio workstation.
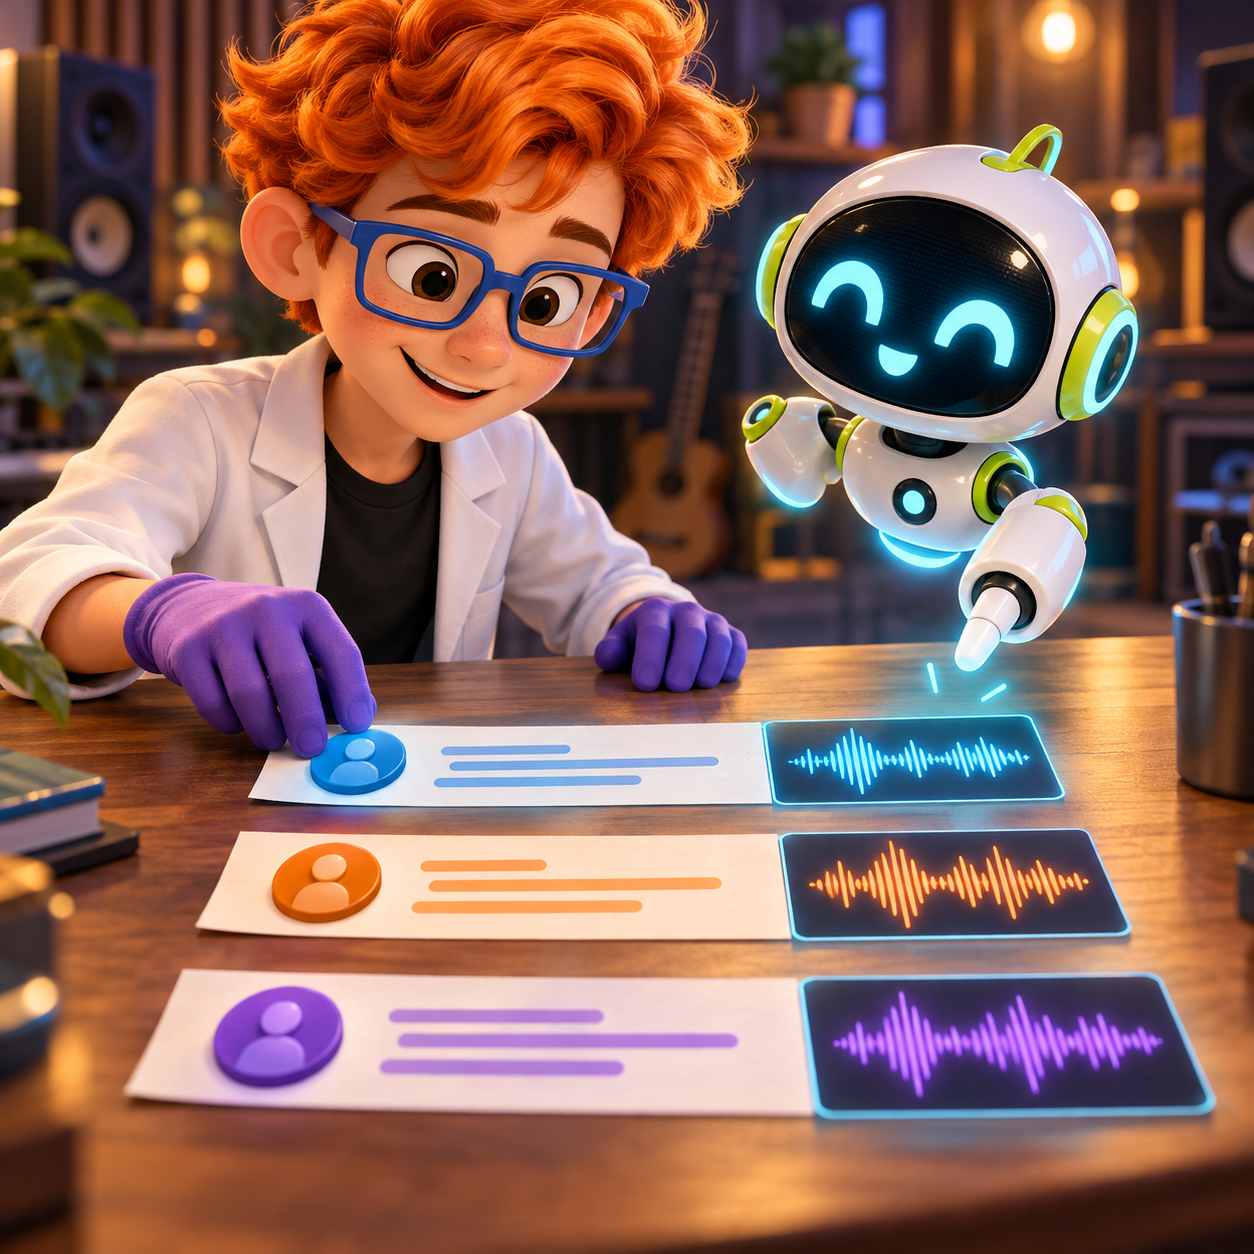
Conceptual mapping of speaker turns to distinct voice treatments, shown as physical cards rather than an application interface.
Verify the request shape in the current docs
The Vercel model page shows Drama 3 in a generateSpeech example through the AI SDK. The request includes a model, text, and voice identifier. Treat that as a concrete starting point for a single-voice call; separately verify the supported syntax for multi-speaker dialogue and direction before you design around it.
import { experimental_generateSpeech as generateSpeech } from 'ai';
import { gateway } from '@ai-sdk/gateway';

const result = await generateSpeech({
  model: gateway.speechModel('fish-audio/drama-3'),
  text: 'Hello from the Vercel AI Gateway!',
  voice: '933563129e564b19a115bedd57b7406a',
});
The sample demonstrates how to select the model and voice and receive generated audio. It does not, by itself, establish how to encode a cast of speakers in one call, whether voice IDs are portable across accounts, or what retry and streaming behavior your app should expect. Read the current model docs and run a small request with the exact input format you plan to ship. If separate calls are needed for separate turns, measure how your app stitches the resulting clips and handles pauses; do not promise one-call dialogue until that path is verified.
11 production screens. Login and database wired.
The SaaS Dashboard Kit includes login, a database, and a working dashboard. Live demo at saas.otf-kit.dev.
Build a small evaluation before a broad feature
Use the same script for every test so model or prompt changes are comparable. Make three short cases: a neutral exchange, a scene with a clear emotional turn, and a script with names or words your users commonly need pronounced correctly. For each case, save the script version, selected voice identifiers, direction text, model, and generated audio. This gives the team a record it can compare instead of relying on “the latest take sounded better.”
Listen for a few things deliberately:
- Speaker separation: Can a listener tell who is speaking without seeing the script?
- Direction following: Do pacing, pauses, and emotion change where requested, without spreading into unrelated lines?
- Text fidelity: Are the spoken words, names, and punctuation cues understandable and consistent with the script?
- Editability: Can a user regenerate one line without losing approved lines or changing another speaker’s voice?
- Product behavior: Does your app expose a useful failure state when generation fails, times out, or returns audio that does not match the requested line?
These are product checks, not a model leaderboard. A voice can sound polished in a demo and still be difficult to control in a repeated workflow. Keep the original script and the generated output paired so a reviewer can hear whether a change improved the intended dimension.
Conceptual illustration of reviewing and editing one generated dialogue line; not a product screen or OTF integration.
Budget for iteration, not just the first render
The Vercel AI Gateway model page currently lists Drama 3 at $10 per million input characters. At that listed rate, a 10,000-character input is about $0.10 for one generation before any other applicable charges. The cost of a feature depends on how much text users submit and how often they regenerate it. A product that offers unlimited “try again” can spend several times the first-render estimate on the same scene.
Estimate your own usage with a simple calculation:
characters submitted × listed price per character × generations
Use the actual script lengths and regeneration counts from your workflow. Keep the model and usage price visible in the evaluation notes, because the listing may change and preview terms can differ from a later generally available product. Do not infer quality or latency from price, and do not promise users a fixed cost until you have measured their real pattern.
Keep generation behind your application boundary
Put the model call on your server so the browser never receives a provider credential. The app should own authentication, request limits, the script record, the chosen voice mapping, and the generated result. Before sending a request, validate the script and reject empty or excessively large inputs according to the limits your product sets. Store only the data needed to let the user review, download, or regenerate the result.
Also decide what happens when a user changes a line after approval. Regenerating the whole script may change delivery in lines that were already accepted. If the API supports turn-level generation, keep the unchanged audio and regenerate only the edited turn; if it does not, make that limitation clear and let users review a complete replacement before it becomes the current version.
The model is in preview, so build a seam around the provider call rather than spreading provider-specific request details through UI components. Keep the app’s script and speaker concepts independent of the exact API payload. That makes it easier to change the integration if the model, request format, availability, or price changes. This is an engineering boundary, not a promise that another provider will produce equivalent audio.
Make the first release narrow
Start with one workflow: a user writes or pastes a short scene, assigns a small set of voices, adds directions, and reviews the resulting audio. Avoid adding a voice marketplace, long-form upload flow, public sharing, or collaboration controls until the core loop works. The first release should answer whether users can reliably create and revise the dialogue they came for.
Keep a human review step before audio becomes public or is sent to customers. Give reviewers the script alongside the generated file, and let them replay each turn. If the model changes a line in a way that alters the meaning, the reviewer should be able to reject that take rather than silently accept it. Make sure your product terms and provider terms cover the content and voices you allow users to submit.
If your product also needs spoken assistant replies or audio input, keep those use cases distinct. Our OpenRouter voice-app guide covers file-based voice input and spoken replies; script-directed, multi-speaker narration is a different product workflow with different editing needs.
A practical next step
Before adding a settings panel, send one short, representative script through the current documented request path. Record the input, voice choices, direction, output, cost, and what a reviewer would change. Then test an edit and a retry. If the separate-speaker workflow is not clearly supported in the current docs, prototype it in a small server-side boundary and confirm the request shape before designing the user-facing controls.
If you need an editable app shell for a dashboard or script-review workspace, the SaaS Dashboard kit includes authentication, teams, and data tables at a one-time $99 price. It is an optional UI starting point; it does not include Drama 3, Vercel AI Gateway, or text-to-speech integration.
Sources
- Vercel AI Gateway: Drama 3 API, pricing, and playground. The page identifies Drama 3 as a Fish Audio text-to-speech model in preview, describes its natural-language performance directions and multi-speaker use case, shows an AI SDK request, and lists the current input price.
Ship the product, not the setup.
- 11 production screens — auth, team, analytics, and settings
- Login and a real database are wired in
- AI configs pre-tuned so your agent extends instead of regenerates