
Add consented voice cloning to a TypeScript app with Sarvam AI
A voice sample is easy to collect. Turning it into a safe, useful feature is the harder part.
If your app needs spoken replies in a user’s own voice, the integration has to do more than send audio to a model. It needs clear permission, a durable identity for the approved voice, an output path that fits the interface, and a way to stop using the voice later.
Sarvam’s TypeScript SDK now exposes beta instant voice cloning methods for conversion, HTTP streaming, WebSocket streaming, and voice management. That gives a TypeScript app several ways to build the workflow. The important choice is how you organize consent, storage, and playback around those calls.
Start with permission and a narrow purpose
Treat a voice sample as a permissioned asset. Before recording or uploading it, tell the speaker what the app will generate, where the resulting voice can be used, and how they can remove it. Collect affirmative consent before creating a cloned voice. Do not let one user submit another person’s sample simply because they can access the upload form.
Keep the consent record separate from the audio. A practical record can identify the account, the purpose the person approved, the time of consent, and the current status. Avoid storing the sample longer than your product needs. Restrict access to the raw recording and make the deletion path visible in the same settings area where users manage their voice.
This is a product-design baseline, not a substitute for legal review. The API capability does not decide whether you have the rights to a recording or whether a particular use is appropriate. Your app must set those boundaries and enforce them.
Create a saved voice once
For a user who will generate speech repeatedly, a saved voice is easier to manage than uploading the reference recording with every request. Sarvam’s voice-cloning guide describes creating a voice and receiving a voice_id. Store that identifier against the consenting account and the approved purpose, then use it for later generations. Keep the provider API key on your server; the TypeScript SDK reads SARVAM_API_KEY from the environment, and a browser client should never receive that secret.
A minimal application record might contain an internal voice record ID, the provider’s voice_id, the account owner, consent state, creation time, and deletion state. Keep the internal record ID in your product UI. The provider ID is an implementation detail, not a public authorization token. Every request should verify that the signed-in user is allowed to use the voice for the selected feature.
The create-voice response can include an automatically generated reference transcript. Treat that as a useful review aid, not as proof of consent or a guarantee that the sample is suitable. Let the user confirm the voice belongs to them and that the result is acceptable before enabling it for other workflows.
11 production screens. Login and database wired.
The SaaS Dashboard Kit includes login, a database, and a working dashboard. Live demo at saas.otf-kit.dev.
Choose one input path per request
The API supports either a saved voice_id or an inline ref_audio for a conversion request. The guide says to provide one or the other; sending both returns a 400 response. That simple constraint should shape your server-side request builder, so a UI state cannot accidentally submit two sources.
Use a saved ID when the user has created a voice and expects to return to it. Use inline reference audio for a one-time flow where you do not need a persistent voice record. If you support inline audio, make the retention behavior explicit and remove temporary files according to your policy. The voice library and the temporary upload path should not silently become the same thing.
Validate file size and duration before forwarding audio. The guide documents a 50 MB maximum for voice creation, while inline reference audio is limited to 10 MB and 15 seconds. It recommends a 10–15 second recording. Reject invalid files with a useful message before making a paid generation call, and avoid logging raw audio or secrets when diagnosing failures.
Match generation to the experience
The beta interface offers three useful shapes:
- One-shot conversion is the simplest choice when the user submits a complete text and can wait for the finished audio. The response contains base64 audio that your server can decode and return or store.
- HTTP streaming sends audio as sentences become ready. It can reduce the wait before playback for a response that is already known as text.
- WebSocket streaming suits an interactive session where text arrives incrementally or the client needs a continuing stream. The SDK exposes a streaming interface for this path, which requires an event-driven client.
Choose the least complex option that meets the product’s latency needs. A profile narration button usually does not need a persistent socket. A live conversational feature may benefit from one, but it also needs reconnect handling, a clear end-of-session action, and a fallback when the stream closes unexpectedly.
Make the user interface distinguish “generating” from “ready.” For HTTP or WebSocket streaming, include an immediate stop control, keep the text visible while audio arrives, and allow replay only within the product’s retention policy. Do not play speech automatically in a way that surprises people or exposes private content in a shared space.
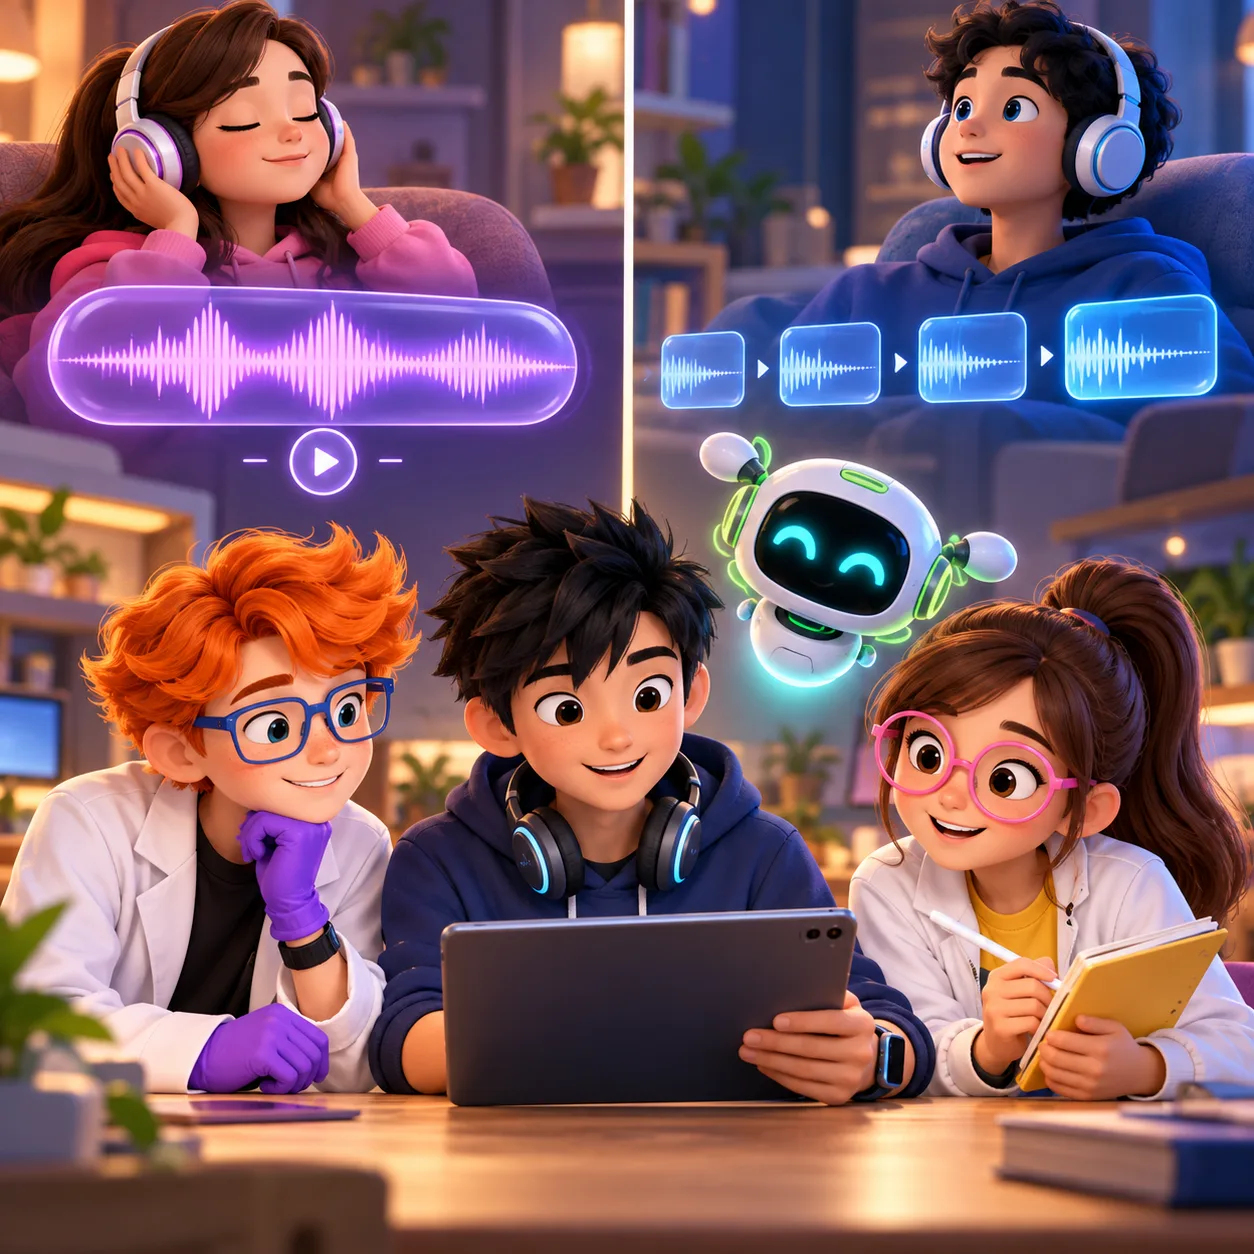
One-shot playback waits for the complete response; streaming can make portions available as they arrive. Conceptual comparison, not a provider interface.
Keep the TypeScript integration on the server
Install the official sarvamai package and create the client in a server-only module. Put SARVAM_API_KEY in the deployment environment, not in a NEXT_PUBLIC_ variable, checked-in file, or client bundle. Route requests through an authenticated endpoint that checks account ownership, consent status, allowed purpose, input limits, and the user’s remaining generation budget before calling Sarvam.
The SDK changelog names the TypeScript methods voiceCloning.convert, voiceCloning.convertStream, voiceCloningStreaming, and voice lifecycle operations such as createVoice, listVoices, getVoice, and deleteVoice. The exact call and return types can change while the feature is beta, so pin the SDK version you tested and follow the current TypeScript reference for its request fields. Do not copy Python parameter names into a TypeScript call and assume they match.
Handle provider errors deliberately. A malformed request should become a clear validation message; a timeout should not create a second generation automatically; and a failed stream should release its socket and temporary buffers. Log a request ID, operation, duration, and outcome, but leave out API keys, reference audio, and generated audio. This gives support enough information to investigate without turning logs into a second audio store.
Make deletion part of the feature
Voice creation is only half of the lifecycle. The SDK exposes list, get, and delete operations. Build a settings view where users can see their saved voices and remove one. When deletion starts, disable new generations for that voice, call the provider deletion method from the server, and then mark the internal record as deleted after you receive confirmation. If the provider request fails, show a retryable state instead of claiming the voice is gone.
Sarvam’s guide says the free plan supports up to five cloned voices, while paid plans are not capped; deleting a voice frees a slot. Generation is billed by text character. Those limits make it useful to show the user which voices are active and to place a server-side budget guard before generating long text. Consider a maximum input length, a per-account daily allowance, and a preview step before an expensive request. Surface the applicable plan limit instead of letting a provider error be the first sign that the account ran out of capacity.
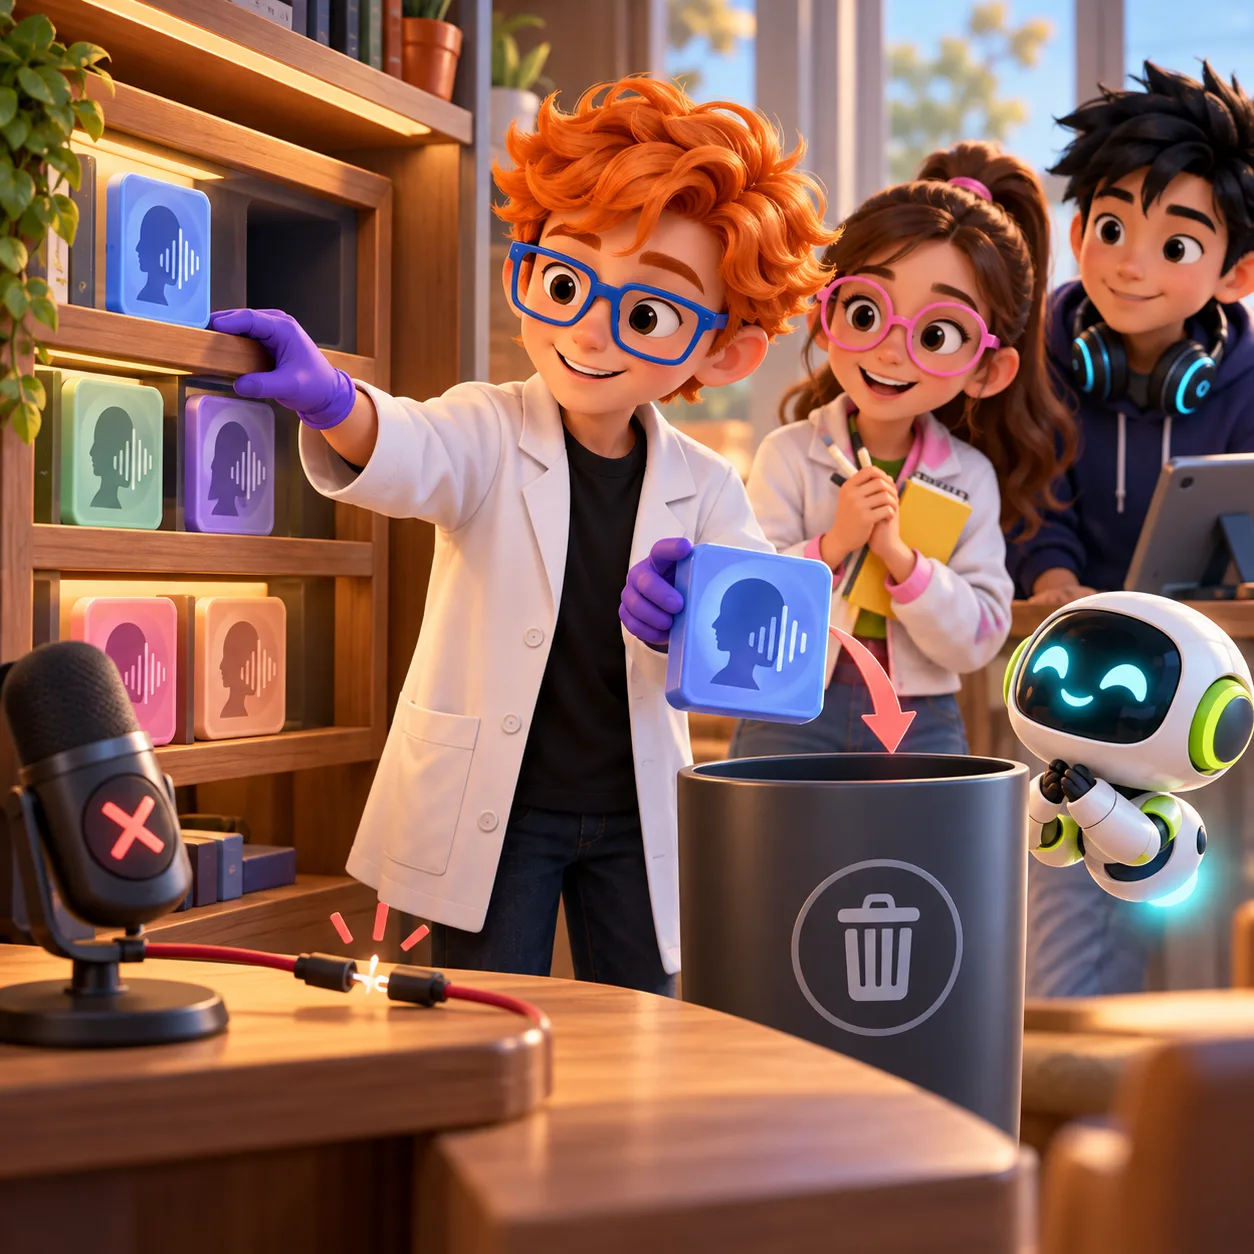
Conceptual withdrawal flow for a saved voice. The app must disable future use and confirm provider deletion before claiming removal is complete.
Ship a small, testable first version
Start with one consented voice, one server endpoint, and one-shot generation. Test ownership checks with two accounts, verify the API key never appears in browser assets or logs, and confirm that an unconsented or deleted voice cannot be used. Then add HTTP streaming if the wait for complete audio is harming the experience. Add WebSocket streaming only when the product has a real incremental interaction to support.
Track the time to first audio, total generation time, failure rate, and characters generated. Those measurements tell you whether streaming is helping and where to add limits. Pair them with a clear consent state and deletion test; a fast voice endpoint is not ready if it keeps working after a user has withdrawn permission.
If you are building the surrounding account screens and app shell, the SaaS Dashboard kit is an optional starting point. It does not include Sarvam, voice cloning, audio storage, or this integration; you would build and verify those pieces yourself. For another voice-oriented workflow, see how to add file-based voice input and spoken replies to an OpenRouter app.
Sources
- Sarvam AI: Instant Voice Cloning overview and API guide — beta endpoints, saved voice lifecycle, input limits, plan limits, and generation billing.
Ship the product, not the setup.
- 11 production screens — auth, team, analytics, and settings
- Login and a real database are wired in
- AI configs pre-tuned so your agent extends instead of regenerates