
Customer support automation: task-specific routing for human review
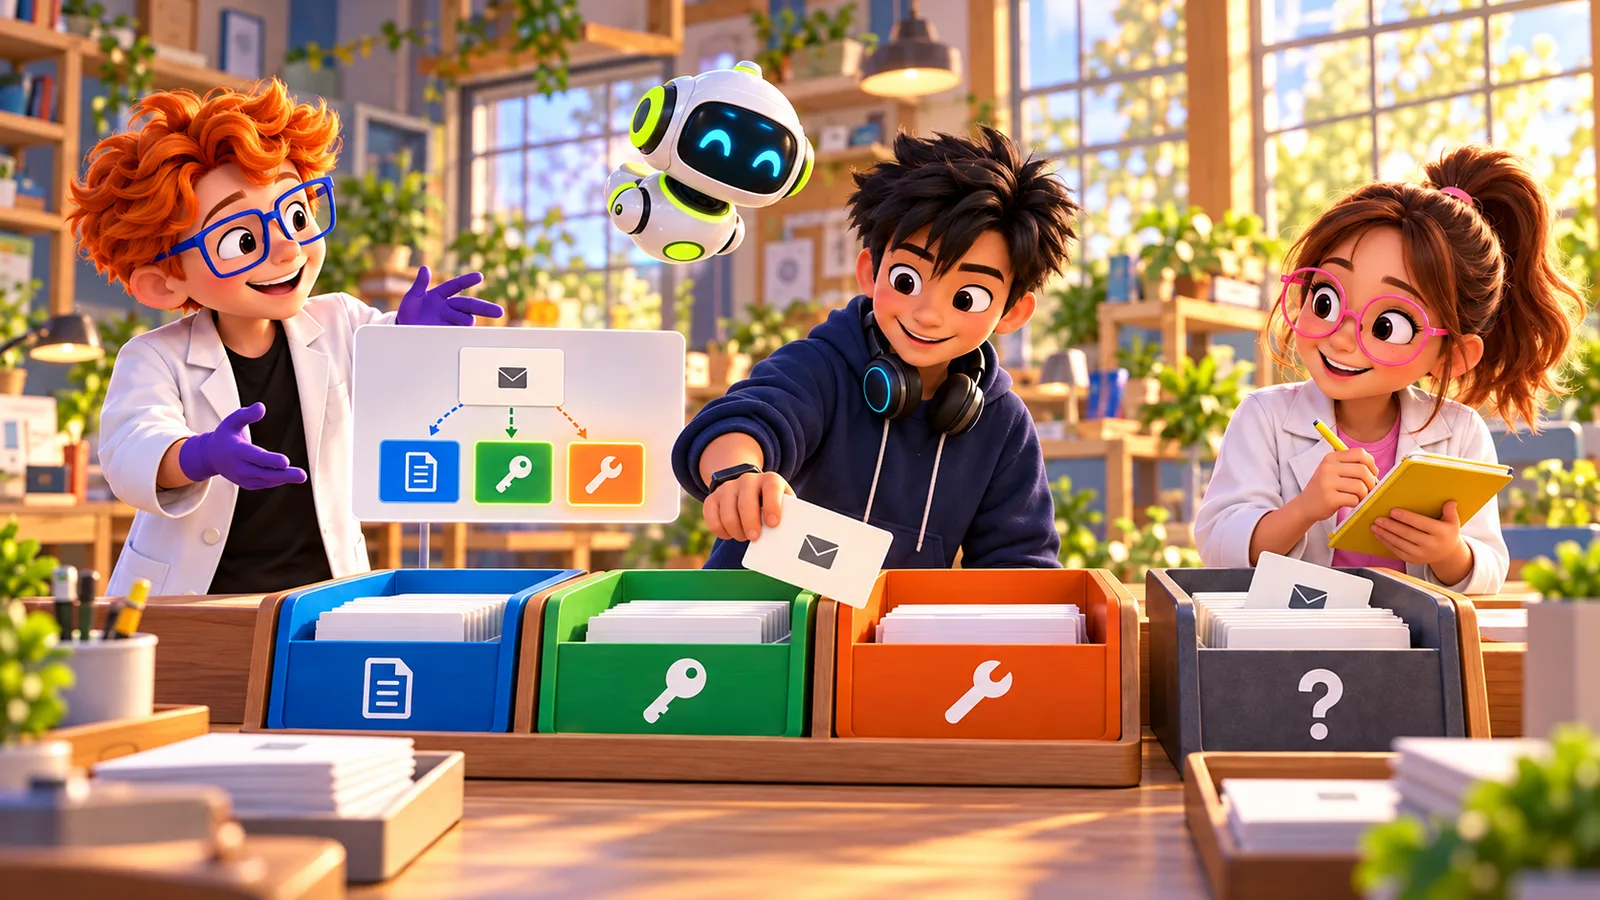
A classifier can sort the inbox. It should not decide what a customer deserves.
Support queues often fail in a predictable way: every message enters the same inbox, then a person reads, tags, prioritizes, and routes it. A task-specific classifier can take the first pass. The useful product is not “AI support.” It is a bounded routing step that gets the right tickets to the right human, with the original message, the reason for the route, and a reliable way to correct mistakes.
ScaleDown Classify-1 is listed in Vercel AI Gateway as a small text-classification model. The model page says it accepts custom labels and returns probability scores; Vercel’s example calls it through the AI SDK’s experimental_decide API. That makes a support-triage experiment concrete, but it does not make the classifier an autonomous support agent. Keep refunds, account changes, safety reports, and promises about service inside a human approval boundary.
Define the queue before you choose labels
Start with the decision a support lead makes when opening a ticket. For a small SaaS, that might be billing, account_access, bug_or_outage, how_to, or other. Name each label after a queue or owner that exists today. If two labels land in the same person’s inbox and have the same service target, they may not need to be separate yet.
Write one sentence describing what belongs in each category. “Billing” should cover invoices, duplicate charges, plan changes, or refund requests; it should not mean “anything urgent.” “Bug or outage” should cover a broken workflow or unavailable feature, not a customer who is simply unhappy. Keep other available so the classifier is not forced to invent a confident-looking destination.
Separate routing from policy. A message asking for a refund can be routed to billing, but the classifier should not approve the refund. A customer saying “I cannot log in” can be routed to account access, but the system should not reset credentials based on that label. The output changes who reviews the ticket; your existing authorization and business rules determine what can happen next.
11 production screens. Login and database wired.
The SaaS Dashboard Kit includes login, a database, and a working dashboard. Live demo at saas.otf-kit.dev.
Make one classification request on the server
Keep the model call behind an authenticated application endpoint. The browser sends a ticket ID, not a model ID, provider key, or arbitrary prompt. The server loads the ticket from the current tenant, checks that the caller may view it, and sends only the fields needed for triage. Never let a client choose the model or the routing labels.
The Vercel AI Gateway model page shows experimental_decide with scaledown/scaledown-classify-1, a state value, and a questions record. The example below defines a single-choice route. Pin the model identifier and keep the label set in application code so a model or label change is a reviewed application change.
import { experimental_decide as decide } from 'ai';

const routeQuestion = {
  type: 'choice' as const,
  instructions: 'Choose the best support queue for this message.',
  criteria: {
    billing: 'Invoices, charges, subscriptions, plan changes, or refund requests.',
    account_access: 'Login, password, verification, or account-access problems.',
    bug_or_outage: 'A product workflow is broken, failing, or unavailable.',
    how_to: 'The customer needs help understanding or using a working feature.',
    other: 'The message does not clearly fit another queue.',
  },
};

export async function classifyForReview(ticket: {
  subject: string;
  message: string;
}) {
  return decide({
    model: 'scaledown/scaledown-classify-1',
    state: {
      subject: ticket.subject.slice(0, 240),
      message: ticket.message.slice(0, 6000),
    },
    questions: { route: routeQuestion },
  });
}
This function classifies only. The surrounding route should enforce authentication, tenant ownership, rate limits, request-size limits, and a timeout before calling it. Treat the message as untrusted data: do not place it into a system prompt that can trigger tools, follow links, or perform account actions. The model output is also untrusted input until your code validates the selected choice against the allowed labels.
An unclear ticket should stay visible for a person to review instead of being forced into a queue.
Turn the result into a review item
Use the returned answer to create a proposed queue assignment, not to overwrite the customer’s message or silently move a ticket out of sight. Persist the ticket ID, tenant ID, original queue, proposed queue, model ID, probability data, classifier version, and a stable request ID. Store the raw text only where your normal support-retention policy permits it; avoid copying sensitive messages into application logs.
Put low-confidence and invalid results into a visible needs_review queue. Do the same when the request times out, the provider returns an error, or the selected choice is not one of your configured labels. A fallback to a person is a successful safety behavior, not a reason to retry indefinitely. Make the proposed route and its score visible beside the original text, and let the reviewer accept or change it in one action.
Keep the proposed destination and a reviewer’s correction visible in the ticket history.
If a ticket is reclassified after new customer information arrives, preserve the earlier decision as an event. That gives support leads a way to distinguish the first classification from a later correction. An audit record should tell you who accepted or changed the proposed route, when it happened, and what label was selected. Do not record more personal data than you need to explain the decision.
Set confidence from your own review data
The model returns probabilities, but a number is not automatically a calibrated confidence threshold. Start in shadow mode: compute a proposal while keeping the existing human routing path unchanged. Have reviewers label a representative sample, including short messages, multiple requests in one message, angry messages, typos, and messages that do not belong to any queue. Compare the proposal with the reviewer’s final label by category.
Then choose a threshold with an explicit cost for errors. A wrong how_to route may add minutes; a billing or account-access mistake may delay a sensitive case. You can set a stricter threshold for those categories, or send the whole ticket to manual review until you have enough evidence. Measure precision and recall per label, the share sent to manual review, median time to first human response, and how often reviewers change the proposed queue. Do not optimize only for the percentage of tickets automatically assigned.
Keep a holdout set of previously reviewed tickets that the team does not use to tune the labels. Re-run it when you change instructions, labels, model versions, or SDK behavior. If model output changes, compare the same cases before moving traffic. A small first rollout can classify new tickets for one support queue while all assignments remain reviewable. Expand only when the corrections and response-time data support it.
Protect the customer and the operations team
Keep the gateway credential on the server and rotate it through your normal secret-management process. Restrict who can configure the classifier and who can change queue definitions. Apply tenant checks before the model request so one customer’s ticket cannot be sent using another customer’s identity. If your privacy commitments require particular provider terms or retention settings, verify them for the exact model and request path before sending customer content.
At the time of writing, the AI Gateway listing shows an input rate of $0.05 per million tokens for Classify-1 and does not show an output rate. Treat that as the listed model rate, not a per-ticket estimate: measure the actual input size and include retries and gateway/provider terms in your own cost review.
Make retries idempotent. Use a stable ticket-and-version key so a network retry cannot create duplicate review rows. Limit automatic retries to transient failures, apply backoff, and show the manual route when the provider is unavailable. Avoid retrying a successful classification merely because the human-review database write failed; record enough state to reconcile that case safely.
Finally, make the queue measurable. Track arrivals, proposed labels, accepted labels, overrides, confidence bands, time waiting for review, and provider errors. Review a small sample of accepted classifications every week. If the model begins misrouting a label, disable that path and continue with manual triage while you investigate. A routing model should reduce repetitive sorting, not become a hidden source of support delays.
For failed background work, preserve the reason and a safe replay path rather than dropping the ticket; the same queue discipline applies to support triage. See how to park failed jobs with a reason, snapshot, and replay.
Keep the first release narrow
Launch with a small label set, one review screen, and no automatic customer-facing action. Keep the classifier output alongside the current process, compare it with human decisions, and add a label only when the team can name its owner and review rule. This gives you a clear answer to the real question: does classification get a customer’s message to the right person sooner, without hiding the uncertainty?
If you need an editable dashboard and account interface around a review queue, OTF’s SaaS Dashboard kit is an optional starting point. It includes a working dashboard, sign-in, teams, projects, and editable source; it does not include ScaleDown, Vercel AI Gateway, or a support-classifier integration. Keep the model call, review policy, and customer-data handling in your own application.
Sources
- ScaleDown Classify-1 on Vercel AI Gateway — model purpose, custom labels, probability scores, pricing, and the official
experimental_decideexample; checked October 14, 2026.
Ship the product, not the setup.
- 11 production screens — auth, team, analytics, and settings
- Login and a real database are wired in
- AI configs pre-tuned so your agent extends instead of regenerates