
MiMo V2.6 on AI Gateway: pick Pro vs Flash vs UltraSpeed for coding agents
Xiaomi’s MiMo V2.6 Pro, Flash, and Pro UltraSpeed are on Vercel AI Gateway as of September 21, 2026. Three IDs. One gateway surface. The buyer question is which id you pin for agentic coding versus interactive UltraSpeed — and what budget and failover rules sit next to that pin.
This is not a try-the-playground recap. Pin xiaomi/mimo-v2.6-* in agent config or the AI SDK, document a Pro / Flash / UltraSpeed tier policy in the owned repo, and wire gateway budgets and failover beside the pin. Same discipline as Gemini Arena label versus API pin: the picker label is not the pin.
What landed on AI Gateway
MiMo V2.6 combines coding, reasoning, and tool use with native text, image, audio, and video understanding. Its 1M token context is aimed at long repositories, tool traces, and multi-session agent work. Structured outputs and up to 128K output tokens are part of the same changelog commit.
The three Gateway model ids are explicit:
| Workload | Model id | Checkpoint shape (changelog) |
|---|---|---|
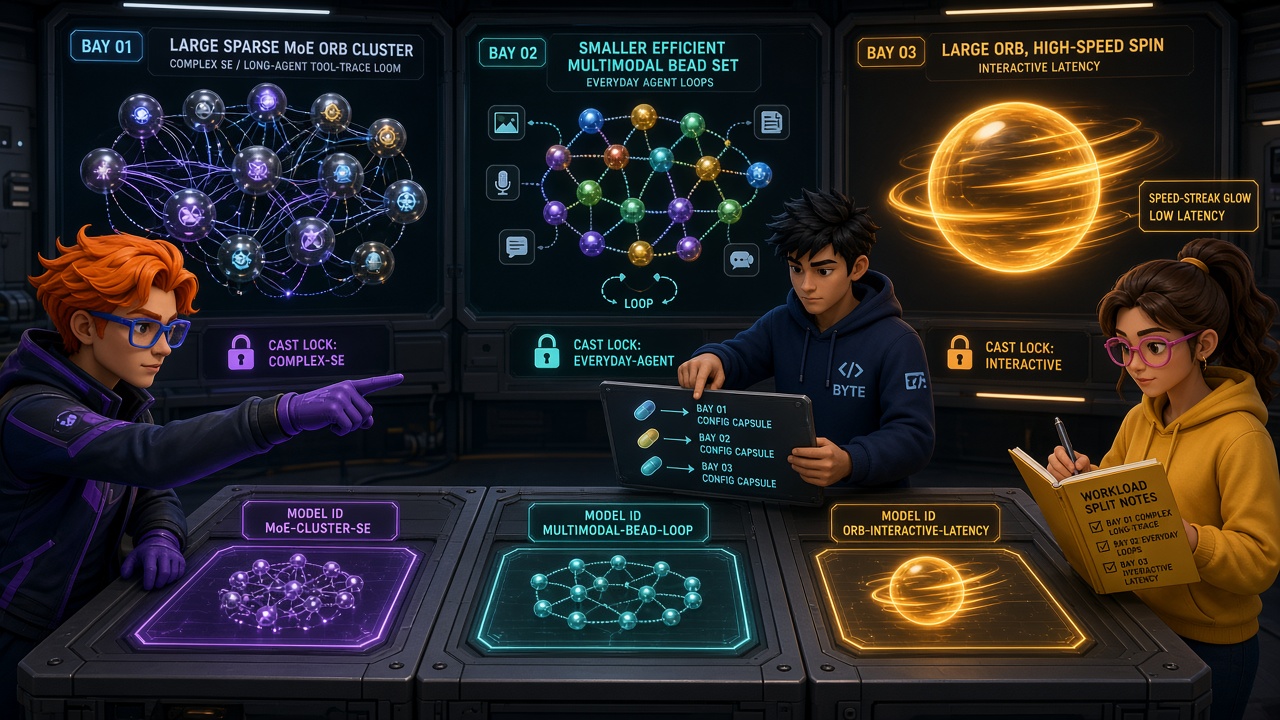
| Complex software engineering and long-running agents | xiaomi/mimo-v2.6-pro | 1.02T total / 42B activated per token (sparse MoE) |
| Efficient multimodal + everyday agents | xiaomi/mimo-v2.6-flash | 309B total / 15B activated per token |
| Interactive / latency-sensitive Pro | xiaomi/mimo-v2.6-pro-ultraspeed | Pro capabilities at up to 20× output speed |
Copy those strings into config. Do not invent a fourth id or paste a marketing name into the model field.
Hold the gaps. The changelog does not publish list prices, cache rates, or millisecond latency. It does not claim UltraSpeed changes quality versus Pro — only output speed, up to 20×, for interactive and latency-sensitive workflows. Treat Flash as the efficiency tier for multimodal automation and everyday agents, not as a silent substitute for Pro on complex software engineering.
Tier policy that belongs in the repo
Owned repos need a written tier map next to the pin, not a sticky note in Slack.
Pro owns complex software engineering and long-running agent loops — multi-file refactors, long tool traces, and sessions that lean on the 1M context. That is the default pin when the agent’s job is hard SE work and you are willing to pay for the larger sparse MoE (1.02T / 42B activated).
Flash owns efficient multimodal automation and everyday agent workflows. Use it when the path is multimodal or routine and you want the smaller activation footprint (309B / 15B). Do not “save cost” by routing Pro-shaped long agents to Flash without a replay window — the changelog separates those workloads on purpose.
Pro UltraSpeed owns interactive and latency-sensitive paths that still need Pro capabilities. Same capabilities as Pro at up to 20× output speed. Pin it for IDE turns, live review loops, and any surface where wall-clock output speed is the product constraint. Keep Pro (standard) for overnight or batch-shaped long agents where speed is not the bottleneck.
Write the map as config the agent can read: which route uses which id, who may change it, and which gateway API key budget covers which tier. That is the durable action — not swapping the playground model once.
Same component. Web and mobile. One codebase.
The free, open-source SDK gives you components that work the same on web and mobile — one codebase. github.com/otf-kit/sdk
Pin with the AI SDK
The changelog’s AI SDK example pins Pro through generateText:
import { generateText } from 'ai';

const { text } = await generateText({
  model: 'xiaomi/mimo-v2.6-pro',
  prompt: 'Review this migration plan and identify any missing steps.',
});

console.log(text);
For Flash or UltraSpeed, change only the model string to xiaomi/mimo-v2.6-flash or xiaomi/mimo-v2.6-pro-ultraspeed. Keep the pin in one module or env-backed constant so tier policy stays searchable. If you already call models through AI Gateway on other launches — for example Gemini 3.8 Live on AI Gateway — reuse the same gateway key and reporting path; swap the id, not the control plane.
Coding agents: Claude Code, Codex, and fx
For Claude Code, Codex, or fx on MiMo V2.6 via the Gateway, the changelog path is the same setup command, then a model picker.
Run:
npx vercel ai-gateway setupThe CLI detects installed agents, provisions an AI Gateway API key, and writes config. Setup turns on gateway model discovery so /model lists the full catalog. Pick MiMo V2.6 Pro, Flash, or Pro UltraSpeed there.
Codex can also start directly on Pro with codex --model xiaomi/mimo-v2.6-pro. fx users install with the fx setup script, run fx in the project, connect with /setup (Sign in with Vercel or paste an AI Gateway key), then /model xiaomi/mimo-v2.6-pro (or Flash / UltraSpeed).
Alternatively, install the latest Vercel CLI and run vercel ai-gateway setup, then select xiaomi/mimo-v2.6-pro, xiaomi/mimo-v2.6-flash, or xiaomi/mimo-v2.6-pro-ultraspeed in the agent. The pin still belongs in your team’s written tier policy — picker convenience is not a substitute for an in-repo id.
Chat Completions through the Gateway base URL
OpenAI-compatible Chat Completions go through https://ai-gateway.vercel.sh/v1 with AI_GATEWAY_API_KEY. The changelog’s Flash example also passes reasoning effort:
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["AI_GATEWAY_API_KEY"],
    base_url="https://ai-gateway.vercel.sh/v1",
)

completion = client.chat.completions.create(
    model="xiaomi/mimo-v2.6-flash",
    messages=[{
        "role": "user",
        "content": "Review this migration plan and identify any missing steps.",
    }],
    extra_body={"reasoning": {"effort": "medium"}},
)

print(completion.choices[0].message.content)
Swap the model id for Pro or UltraSpeed when the tier policy says so. Keep base_url and the gateway key stable. Put reasoning effort in the same policy note if your agents rely on it — do not leave medium as an undocumented client default.
Budgets and failover next to the pin
AI Gateway is not only a model catalog. The changelog states it provides a unified API for calling models, tracking usage and cost, and configuring retries, failover, and performance optimizations for higher-than-provider uptime. It includes built-in custom reporting, budgets for API keys, routing rules, and more.
That list is the second half of the buyer question. Pinning xiaomi/mimo-v2.6-pro without a key budget and failover rule is half a policy.
Practical shape for an owned repo:
- One pin per route. Long agent / complex SE → Pro. Everyday multimodal → Flash. Interactive Pro-shaped UX → UltraSpeed. Encode the three ids in config; reject free-text model strings at the boundary.
- Budgets on API keys. Attach Gateway budgets to the keys that call MiMo so a runaway agent loop cannot burn the whole workspace. Separate keys (or budget lines) for Pro versus Flash versus UltraSpeed if you need independent spend caps.
- Retries and failover. Configure Gateway retries and failover for the routes that must stay up when a single provider path degrades. The changelog’s uptime claim is “higher-than-provider” via those controls — you still have to turn them on for the keys you pin.
- Routing rules + reporting. Use routing rules so interactive UltraSpeed traffic cannot steal the Pro long-agent budget by accident. Custom reporting should tag tier and route so invoices explain which id drove cost.
None of that invents prices the changelog never published. It uses the Gateway controls the announcement actually lists: usage and cost tracking, retries, failover, API key budgets, routing rules, and custom reporting.
What not to confuse with this launch
Xiaomi’s earlier Mimo Code terminal agent is a different product and a different OTF post. This changelog is MiMo V2.6 model ids on AI Gateway — Pro, Flash, and Pro UltraSpeed — not a terminal binary. Do not merge those pins.
Also do not assume UltraSpeed is a separate quality tier. The changelog says it serves Pro at up to 20× output speed with the same capabilities. Quality evals stay on Pro versus Flash; UltraSpeed is a latency pin for Pro-shaped work.
Builder checklist
- Confirm the three ids and capability lines on MiMo V2.6 models now available on AI Gateway.
- Write an in-repo tier policy: Pro for complex SE / long agents, Flash for efficient multimodal / everyday agents, UltraSpeed for interactive Pro paths.
- Pin the exact string in AI SDK
generateText, Chat Completionsmodel, or the agent/modelpicker — never a UI nickname. - Run
npx vercel ai-gateway setup(orvercel ai-gateway setupafternpm i -g vercel@latest) for Claude Code, Codex, or fx; select the id that matches the route. - Set Gateway API key budgets, retries, failover, and routing rules next to those pins; tag custom reporting by tier.
- Replay a small owned-task set on Pro versus Flash before promoting either pin; use UltraSpeed only when output speed is the constraint.
Sources
- MiMo V2.6 models now available on AI Gateway — Vercel Changelog (September 21, 2026): MiMo V2.6 Pro / Flash / Pro UltraSpeed on AI Gateway; coding, reasoning, tool use; native text/image/audio/video; 1M context; structured outputs; up to 128K output tokens; model ids and MoE sizes; AI SDK
generateTextexample; Claude Code / Codex / fx setup vianpx vercel ai-gateway setupand/model; Chat Completions viahttps://ai-gateway.vercel.sh/v1withAI_GATEWAY_API_KEYand reasoning effort; Gateway unified API, usage/cost, retries, failover, API key budgets, routing rules, custom reporting.
Buy once, own the code. Ship with the agent you already use.
- Free, open-source SDK — same component, web and mobile
- Paid kits include AI configs + 40+ tested prompts — your agent reads the whole project
- $99/kit or $149 for everything. No subscription, no sandbox limit.