
OpenRouter Batch for owned repo jobs: when to keep sync vs half-price async
OpenRouter’s Batch API is half-price inference for work that can wait inside a 24-hour window. A provider picks when to run your bundle; you generally pay 50% (and sometimes less) of normal per-token pricing. It ships on more than 70 models. Across 230k+ batches in the two-week beta, the median finished in 7 minutes and 90% finished within an hour.
If you run owned-repo jobs — overnight labeling, ticket summarization, eval scoring, embedding backfills — the useful split is not “always Batch” or “always sync.” Interactive paths stay on the sync API. Background repo jobs POST to /api/v1/batches, pin provider.only when you care which provider runs the bundle, and poll until a terminal status. Unique custom_id values keep one bad row from killing the rest of the job.
What Batch buys you (and what it does not)
Batch is for workloads where highly variable response times are acceptable — labeling a corpus, back-filling embeddings, scoring an eval set, summarizing a ticket backlog, or running one prompt across thousands of rows overnight. The provider schedules inside the 24-hour window and discounts the per-token line.
You do not escape every cost. Web search still bills at standard rates. Images and files must be public URLs. Audio, video, and OpenRouter’s web search plugin are unavailable in batch — keep those shapes on sync until inputs are public URLs or you drop the modalities.
Default routing picks one provider per batch: after allowlist, data policy, and BYOK, OpenRouter chooses the cheapest eligible batch endpoint. With a provider key, BYOK batches route through your key and you pay only the BYOK fee on OpenRouter’s side. Batches appear in the Batches tab (model, provider, status, cost). Inputs and results stay for 30 days, or until DELETE.
The repo-job shape: POST, pin, poll
Submit with POST https://openrouter.ai/api/v1/batches. Required top-level fields: endpoint, model, and requests. Optional: provider as { "only": [...] } and completion_window (only 24h). Serialize endpoint, model, and any provider / completion_window before requests — stream parsing accepts large arrays, and requests first returns 400.
Each requests item is { custom_id, body }. custom_id must be unique in the batch. body follows the endpoint shape: /v1/chat/completions, /v1/responses, /v1/messages, or /v1/embeddings. The batch-level model applies to every row; a per-request model must match or the submit is rejected.
A successful submit returns 202 Accepted with status: "validating" — persisted and queued, not finished. Poll GET /api/v1/batches/:id until terminal: completed, failed, expired, or cancelled. Happy path: validating → in_progress → finalizing → completed. Completed results are inline in that GET; there is no separate download endpoint.
For an owned-repo worker: enqueue, POST, store the batch id, poll (or schedule wake) until terminal. Do not block an interactive HTTP handler on that loop. Chat, IDE agents, and “answer now” paths stay on sync — same discipline as API timeouts and retries for owned AI backends.
11 production screens. Login, database, payments — all wired.
The SaaS Dashboard Kit ships everything already connected. Nothing to set up. Live demo at saas.otf-kit.dev.
When to keep the call on sync
Keep sync when any of these hold:
- The caller is waiting in the UI or an agent turn that must return before the user moves on.
- You need OpenRouter-orchestrated web search, audio, video, or non-URL image/file inputs that batch rejects.
- You need provider preferences Batch does not accept. On Batch,
provider.onlyis the only provider preference accepted;order,sort,allow_fallbacks, and the other sync preferences are rejected. - You are debugging a single request and want immediate generation feedback, not a 24-hour window.
Batch still finishes fast in practice — median 7 minutes, 90% within an hour in the beta — but the contract you design against is the 24-hour window and provider-chosen scheduling. If your product SLA is “under a few seconds,” Batch is the wrong surface even when the discount is attractive.
Use Batch when the job can accept that window: overnight corpus work, eval sets, ticket backlogs, embedding backfills, and any repo pipeline that already persists state and can resume after a poll. Size is not the only signal; a single-request batch is valid, but if that one request is interactive, sync is still the right call.
Pin provider.only so the job owns the provider
Every request in a batch runs on one provider chosen at submit time. Default cheapest-endpoint routing is fine when cost is the only concern. Repo jobs that need a specific provider’s batch behavior — URL image/file fetch, BYOK billing, data residency — set top-level provider.only before requests.
If none of the listed providers has an eligible :batch endpoint, submit returns 404 instead of falling back. Fail closed: better a loud reject than a silent provider swap. Filter models by the :batch variant before you hard-code a pin.
BYOK still applies: with a provider key, supporting providers route through it. Completed batches report is_byok when that path ran. Keep the same key enabled if you later DELETE a BYOK batch that needs upstream cleanup — missing key yields 409.
custom_id so one bad row never kills the job
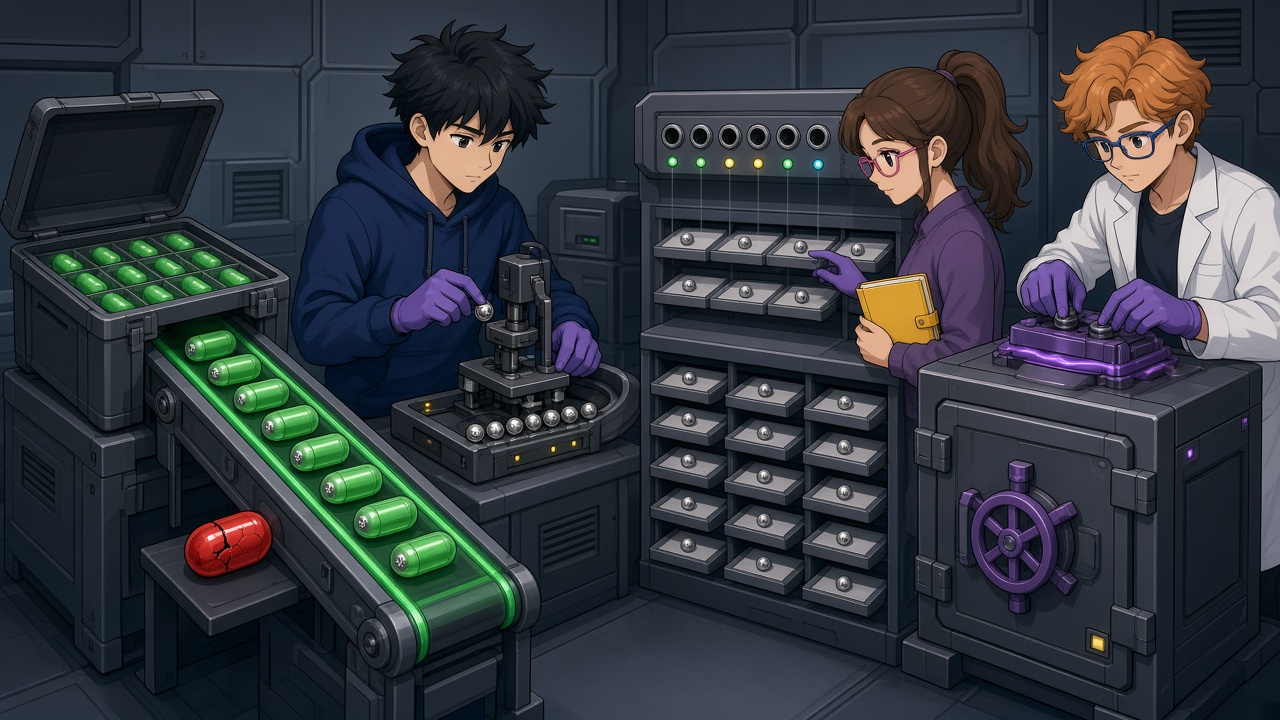
Per-request results are the operational answer to the buyer question. Every result returns independently, so a few bad rows never fail the rest of the job. On completion, each result maps back with custom_id, and exactly one of response or error is populated.
Design the repo job around that contract:
- Generate a stable unique
custom_idper row (ticket id, eval case id, embedding document id) before POST. - Persist the mapping from
custom_idto your domain entity in the same transaction that records the batch id. - On terminal
completed, walkresults, apply successes, and queue retries only for rows witherror— not for the whole batch. - Treat batch-level
failed/expired/cancelledas job-level outcomes; do not confuse them with per-row errors inside a completed batch.
request_counts on the batch object reports total, completed, and failed. A completed batch can show nonzero failed counts while still returning inline results for the successful rows. Your worker should key off custom_id, not assume all-or-nothing success.
Lifecycle hygiene for owned workers
Poll until terminal. While in progress — or after failed, expired, or cancelled — results is null. Only completed returns the inline array. After you ingest results (or decide you no longer need them), DELETE is available for terminal batches (completed, failed, expired, cancelled). Deletion purges OpenRouter-held request and result artifacts without waiting for the 30-day retention window. It is not cancellation: an in-flight batch returns 409.
List endpoints help operators: batches are workspace-scoped, newest first, with optional status filters. List items set results to null; retrieve by id when you need the payload. For human-facing ops and agent triage, keep correlation between your job id, the OpenRouter batch id, and each custom_id in structured logs — the same correlation habit as structured production logs agents can triage.
Limits that change the repo design
Multimodal batch input is URL-only; support depends on the routed provider. Base64 and data: URI images are rejected everywhere. File parts are URL references only where the provider supports them. Audio and video parts are rejected on every provider. OpenRouter-orchestrated search is unavailable; :online variants return 422 on submit. Provider-native web search may pass through when that provider runs the search — that is not the OpenRouter web plugin.
Design repo jobs around text bodies (chat, messages, responses, embeddings), public HTTPS assets when needed, and a pinned provider that supports the asset type. Keep rejected shapes on sync; batch the rest.
Builder checklist
- Decide sync vs Batch per call site: interactive stays sync; durable repo jobs use Batch.
- Confirm the model has a
:batchendpoint; pinprovider.onlywhen provider behavior matters. - POST
/api/v1/batcheswithendpoint,model, then optionalprovider/completion_window, thenrequestsof unique{ custom_id, body }. - Expect
202+validating; poll GET untilcompleted/failed/expired/cancelled. - On
completed, apply inline results bycustom_id; retry only failed rows. - DELETE terminal batches when you no longer need the 30-day retention; use the Batches tab for cost and status.
Sources
Ship the product, not the setup.
- 11 production screens — auth, billing, team, analytics, settings
- Real database, payments, and login — all wired on day 1
- AI configs pre-tuned so your agent extends instead of regenerates