
Filter TwelveLabs Jockey searches by metadata and creation time
A search can be relevant and still be too broad
A video search that matches the right words can still return too much to use. If the same library holds customer interviews, tutorials, product demos, and a stream of newly uploaded clips, a single natural-language query may not answer the actual question: which relevant moments came from this project, in this date window, or in this category?
TwelveLabs’ 15 October 2026 Jockey release adds knowledge-store search filters for user_metadata, enrichment, and created_at. It also documents a hard edge: if the filter conditions match more than 10,000 items, search returns a 422 error with the code metadata_filter_too_broad. The practical change is to design the search around a bounded set of items instead of relying on the text query alone. The release notes list the new fields and the error behavior.
This is useful when you are building a product around a growing media library. A user looking for “the onboarding walkthrough” may also need to say “from the latest release” or “tagged for mobile.” The language query expresses what the clip is about; metadata and creation-time filters express which items are eligible to search.
Separate relevance from eligibility
Treat a search request as two decisions. First, define the eligible slice of the library: the user’s project, content type, category, or time window. Then send the natural-language query that ranks matches within that slice. These are different jobs. A better prompt can improve the meaning of a search, but it cannot replace an application’s access rules or identify which records belong to one customer.
Before wiring a filter into the interface, write down what each field means in your own product. For example, a support-video library might store a project identifier and a content category as custom metadata, while created_at can narrow to a period such as “added since the last release.” A training platform might use a course identifier and a lesson type. The exact metadata keys are your application’s design; the new search fields do not invent those values for you.
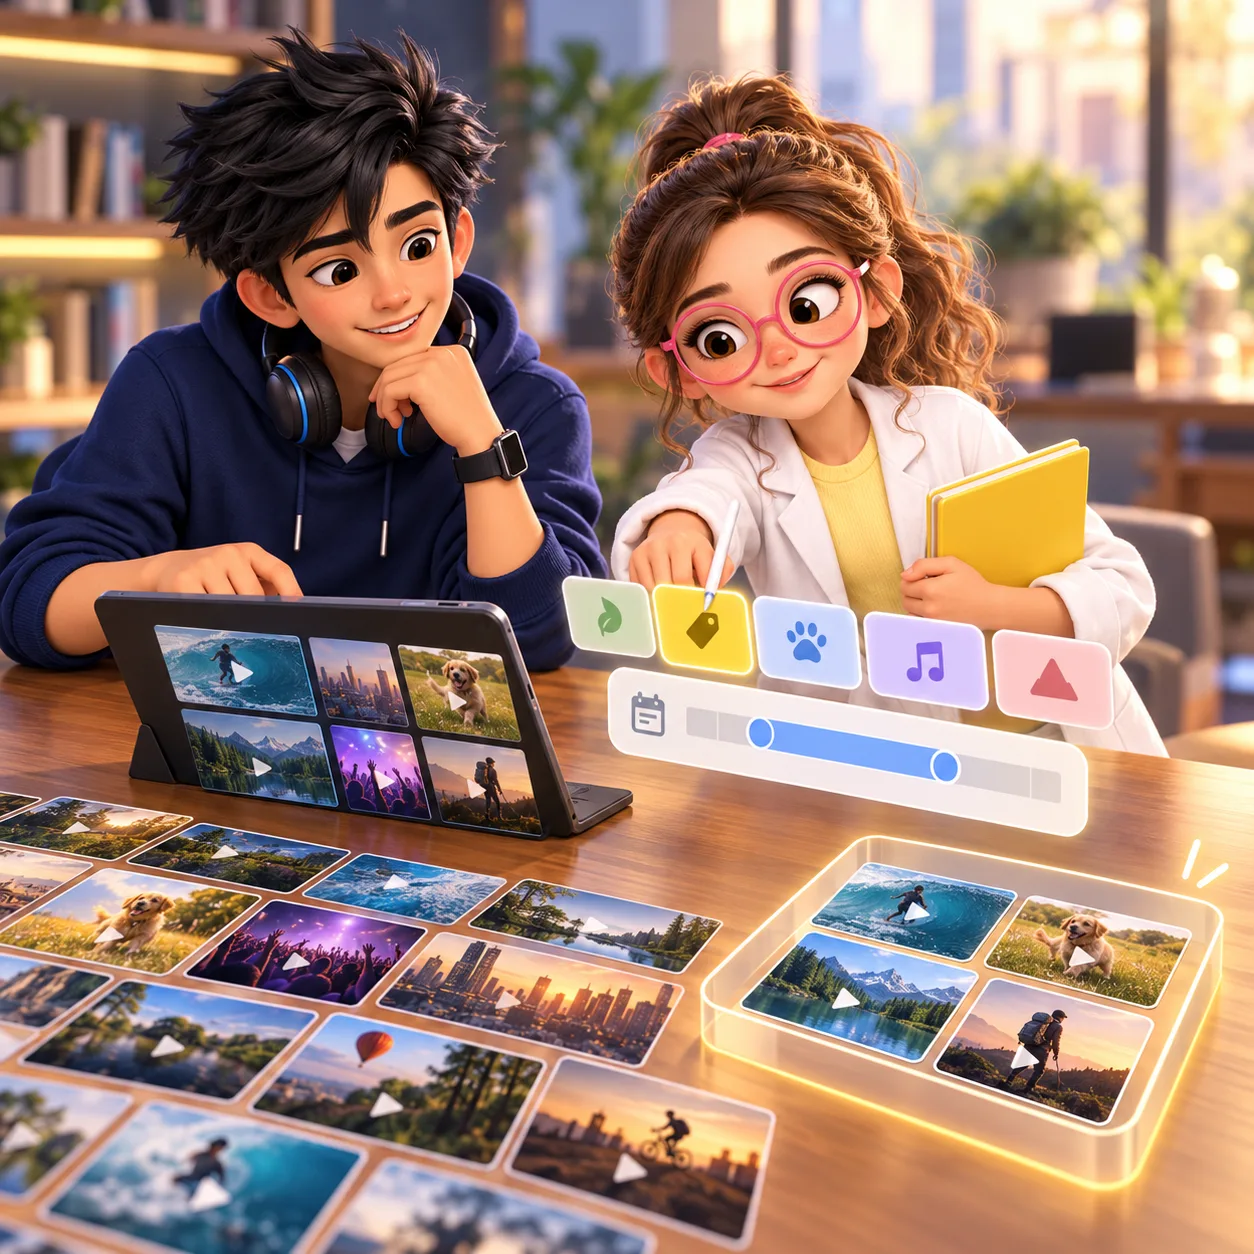
Combine custom metadata and creation-time criteria to scope the clips you want to search.
Keep the filter values in the same system of record as the item they describe. When your ingest flow adds a video, validate and store the metadata alongside the item. If a user changes a category later, decide whether that edit updates the searchable item metadata, the source asset metadata, or both. Those are separate concepts in the API. Avoid treating a display label in your frontend as proof that the backend indexed the corresponding value.
11 production screens. Login and database wired.
The SaaS Dashboard Kit includes login, a database, and a working dashboard. Live demo at saas.otf-kit.dev.
Design for the 10,000-match boundary
The 422 metadata_filter_too_broad response is a signal to make the eligible set more specific. Don’t respond by silently dropping the filter and searching the whole library: that can produce results that are irrelevant to the user or outside the intended workspace.
Build the user experience around narrowing. Start with filters that correspond to values users understand, such as project, content type, or a date range. Show which filters are active, make them easy to remove, and keep the text query visible when the results refresh. If a request still crosses the matching-item threshold, explain that the selection is too broad and suggest one more constraint. The UI should preserve the user’s query while asking for a narrower scope.
A useful fallback is a staged flow: choose a project or collection first, then search within it. If projects can still contain very large libraries, add a date window or a second metadata facet. Keep the error as a distinct application state so it does not appear as an empty result set. “No matches” and “the request matched too many items to run” call for different user actions.
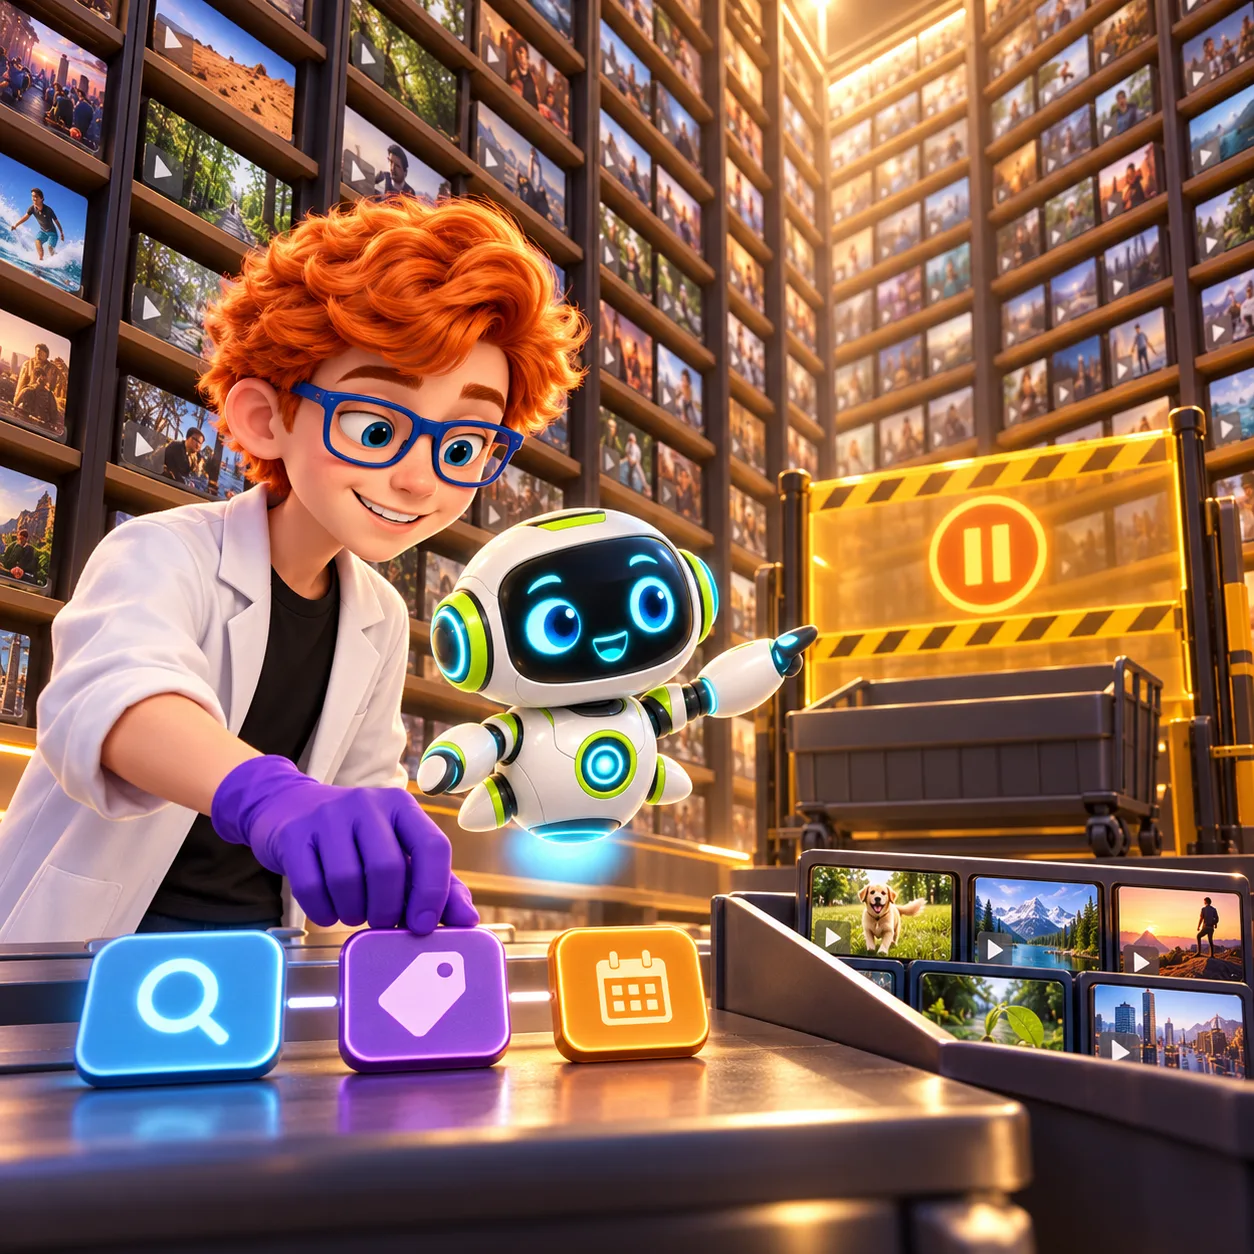
More than 10,000 matching items triggers a 422 metadata_filter_too_broad response; narrow filters before searching.
Keep pagination and filter changes predictable
Search results can span multiple pages. When a user changes the query or any filter, treat it as a new search and clear the old page token. Reusing a token from a different query can make the interface confusing: the next page may belong to the prior search, or the token may no longer be valid. Preserve the active query and filters together, and only request another page for that exact search state.
Also distinguish a result from a video item. Depending on the response grouping, results can represent matching clips or items with their matching clips. Make the UI label clear: a hit may be one moment in a longer video, not a separate uploaded file. When the user opens a hit, use the returned timing information to take them to the relevant part rather than treating every match as a full-video result.
You can test this behavior without guessing at production scale. Create a small fixture library with a few known metadata values and creation times. Check that a query without filters can find the expected clips, then add one metadata constraint and a date boundary. Test the empty state, a changed filter, and a next-page action. Finally, exercise the broad-filter error path in your own integration tests or a controlled test dataset if you can reproduce the documented threshold safely. Don’t fabricate a successful example by claiming to have run a search you have not run.
Keep tenant boundaries outside semantic search
A user-facing search filter is not an authorization mechanism by itself. Enforce the current user’s project or tenant scope in trusted server-side code before sending a request to the provider. Do not accept an arbitrary project identifier from the browser and assume it is safe because it appears in user_metadata.
This distinction matters when a product mixes private and shared videos. A metadata filter can help select items, while your application still needs to verify that the caller is permitted to request those items. Keep the provider credential on the server, validate the tenant and filter values, and return only results your application has authorized. Do not expose private API keys or rely on a hidden filter control as a security boundary.
A practical implementation checklist
- Decide which user decision each filter supports: project, category, owner, or creation window.
- Define and validate metadata at ingestion, using stable values rather than labels that may change.
- Build the provider request from trusted server-side scope plus the user’s allowed filters.
- Keep the natural-language query and the item filters separate in your application state.
- Treat
metadata_filter_too_broadas a request to narrow, not as an empty result or a reason to remove safeguards. - Reset pagination whenever the query or filters change.
- Test clip-level versus item-level results and confirm the interface communicates which one it shows.
- Log the request shape and provider error code without logging secrets or private video content.
Jockey’s new filters are most useful when the application has meaningful metadata and a clear policy for choosing it. If your ingestion process has no stable project, category, or time values, adding filter controls first will only expose that data-quality gap. Start with one workflow, decide how metadata enters and changes, then add controls that help the user narrow the search they actually need.
If you are building the surrounding dashboard, OTF’s SaaS Dashboard kit is an optional editable app shell with sign-in, projects, teams, tables, and analytics screens. The live page lists it at $99 one-time and describes repo access by email after checkout; the kit does not include a TwelveLabs integration. Review the live demo and current pricing, checked 15 October 2026, before deciding whether the shell fits your app. For a related example of presenting table controls, see how to let SaaS users keep their preferred columns. If you want to explore an editable starting point, start here.
Sources
- TwelveLabs v1.3 release notes — Jockey availability, knowledge-store search filters, the 10,000-match threshold, and the
metadata_filter_too_broadresponse; checked 15 October 2026. - OTF SaaS Dashboard kit and pricing — current kit contents, $99 price, and repo-access flow; checked 15 October 2026.
Ship the product, not the setup.
- 11 production screens — auth, team, analytics, and settings
- Login and a real database are wired in
- AI configs pre-tuned so your agent extends instead of regenerates