
Vercel AI Gateway confidence fallbacks: measure before rollout
When a model returns a valid answer with weak confidence, an application often has only two choices: accept it or ask a person. Vercel AI Gateway’s confidence-based decision fallback adds a middle path for experimental_decide: run the configured fallback model when a successful decision matches a confidence condition. The feature is in beta, and a triggered fallback runs a second decision, so both stages are billed.
That makes this a routing control, not a promise that the answer is correct. The useful buyer question is whether a second model improves the decisions that matter enough to pay for its added latency and cost. Keep the existing behavior for routine requests, test the uncertain slice against labeled examples, and put a fallback behind the specific choice or score that warrants another pass.
What the feature changes
Traditional fallback lists handle a model that errors or cannot serve a request. A confidence condition addresses a different case: the primary request completed, but its answer may not meet your confidence bar. Vercel says its existing plain model names continue to catch outright errors as before. The new condition can be combined with other conditions, so a request can be routed based on more than one signal.
For Choice and Score questions, the condition can use confidenceBelow. That confidence describes how concentrated the answer's probability distribution is; it is not the probability that a Boolean answer is true. Boolean questions use probabilityBetween, an inclusive range for P(true). Vercel's example uses 0.6 for a Choice threshold and [0.4, 0.6] for a Boolean band; treat both as syntax examples, not recommended production values. If the question field is omitted, the condition checks every question of the matching type, and any one match triggers the fallback. That broader scope is easy to miss when one decide call contains several questions.
The setting lives in providerOptions.gateway.models as a conditional model object. It must be the first entry, and the array can contain only one conditional object. Plain model-name entries can follow it for execution-error fallback. These are different triggers: the conditional model reruns a successful but uncertain decision; a string entry handles a model that cannot execute successfully. Requests without the conditional object retain their previous behavior. The feature is explicitly beta, so validate the exact request shape and observed behavior in your own environment before relying on it in a critical path.
Start with one decision that has a reviewable answer
Do not enable a second model across every AI request just because a confidence field exists. Pick one decision where an incorrect low-confidence answer has a clear consequence and a fallback can plausibly help. A support-intent choice that routes a billing issue to the wrong team may qualify. A free-form assistant response with no defined labels is harder to evaluate because you cannot consistently determine whether the second stage improved it.
Build a small, representative evaluation set from real request shapes. Remove secrets and personal data before using records for evaluation. For each example, store the input, the expected choice or score, and the production consequence of a wrong answer. Include ordinary cases and the difficult boundary cases your current system mishandles. Keep the evaluation set separate from examples used to tune the prompt or threshold, then use a held-out slice to check that tuning did not merely memorize the first set.
Run the primary model alone first. Record its output, confidence, correctness against the label, and request duration. This gives you the baseline: how often the primary answer is wrong, how those errors distribute across confidence values, and which categories account for the harm. A confidence threshold is useful only if confidence separates cases your fallback can improve from cases it cannot.
Same component. Web and mobile. One codebase.
The free, open-source SDK gives you components that work the same on web and mobile — one codebase. github.com/otf-kit/sdk
Add a conditional fallback narrowly
The shape below follows Vercel’s AI SDK example. The model identifiers and threshold are illustrative; select models available to your project and choose a threshold from your evaluation results.
import { gateway } from '@ai-sdk/gateway'
import { experimental_decide as decide } from 'ai'

const result = await decide({
  model: gateway.decisionModel('typesafe-ai/jev'),
  state: 'I was charged twice and now the app will not load.',
  questions: {
    intent: {
      type: 'choice',
      instructions: 'Which team should handle this?',
      criteria: {
        billing: 'Charges and refunds',
        technical: 'Bugs and outages',
      },
    },
  },
  providerOptions: {
    gateway: {
      models: [
        {
          model: 'openai/gpt-6-astra',
          when: { question: 'intent', confidenceBelow: 0.6 },
        },
      ],
    },
  },
})
The key operational choice is the scope in when. Naming intent keeps the condition attached to that question. If you leave out question, Vercel says the condition checks every Choice or Score question of the matching type, and a single match is enough. Avoid relying on that broad form when a request contains multiple decisions with different risk levels. For a Boolean decision, use probabilityBetween: [low, high]; both bounds are inclusive, and confidenceBelow does not apply to Boolean answers.
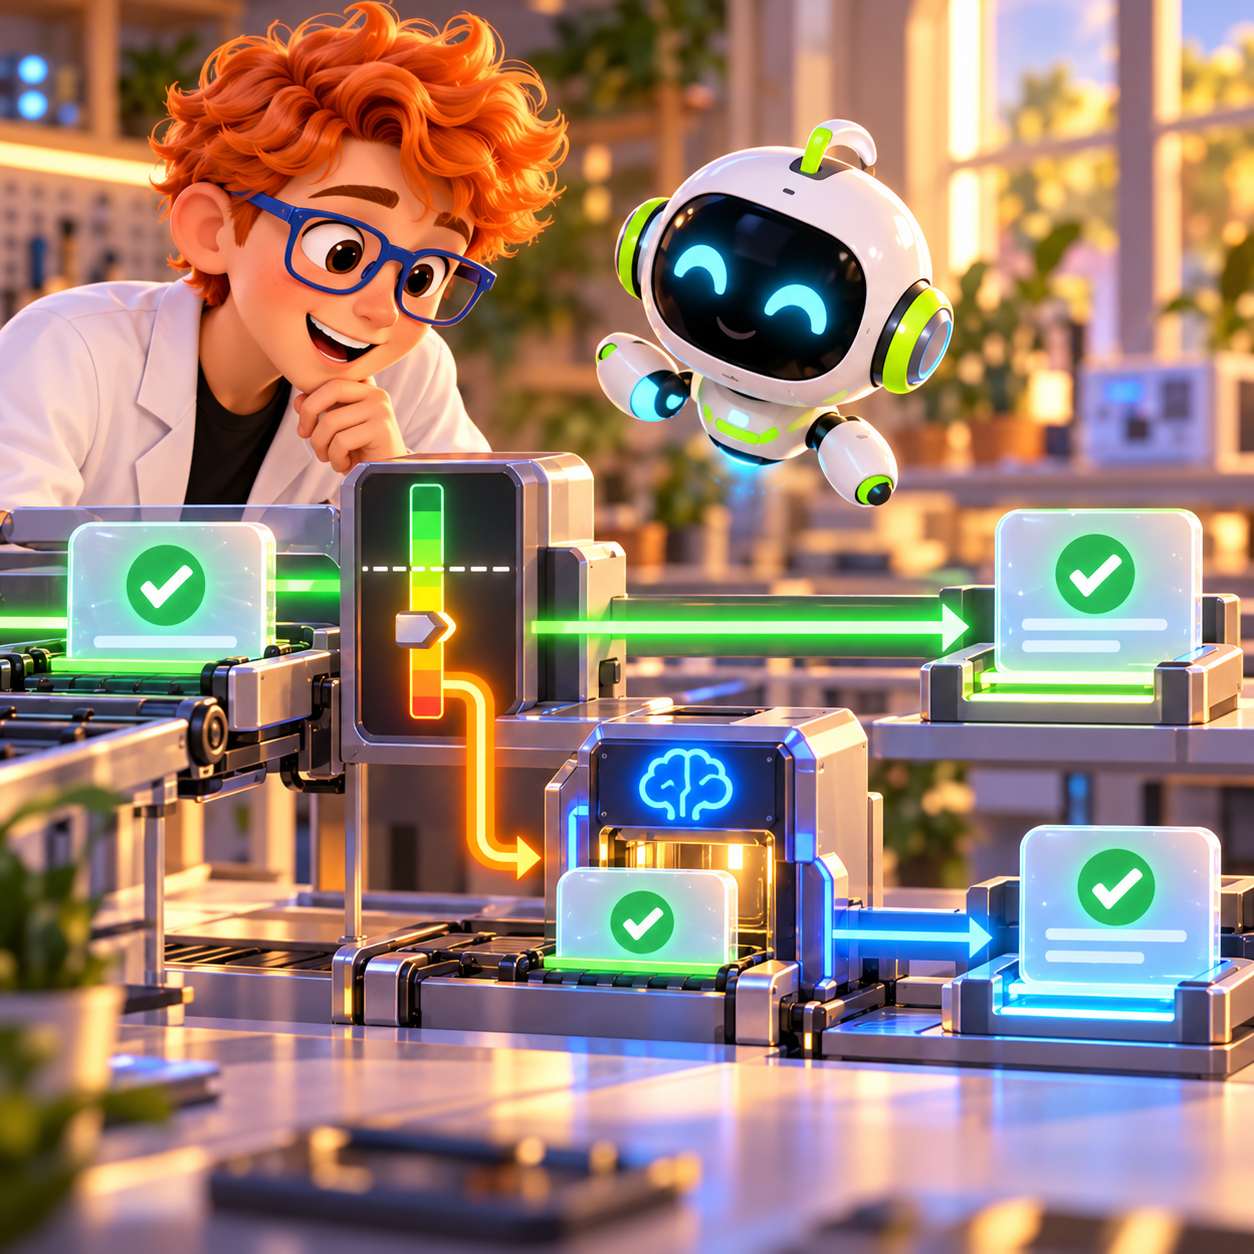
When the condition matches, AI Gateway reruns the complete decision with the original state and all original questions. It returns the fallback result as a whole; it does not merge answers from the first and second stages or evaluate the condition a second time. That means a request has at most two successful decision stages. If the conditional model fails, the request fails rather than returning the primary result. Treat that failure path as part of your application design, especially if the decision gates money, account access, or another consequential action.
Only native decision models report Choice and Score confidence. A language-model fallback returns structured values without a confidence distribution, so do not expect a second confidence score to validate its answer. Vercel also treats a missing or non-finite primary confidence as a conservative match. Inspect routing metadata and the returned model in the SDK response:
console.log(result.response.modelId)
console.log(result.providerMetadata?.gateway?.routing)
Measure the second stage before rollout
Compare three paths on the same held-out examples: primary model only, fallback on every request, and fallback only when the condition triggers. The always-fallback path helps establish the outcome the second model could deliver on that set; it is a measurement baseline, not necessarily a production design. For each path, count correct decisions, harmful errors, fallback triggers, and requests where the fallback changes the answer from wrong to right or right to wrong. Since the fallback replaces the entire answer set, also check every question in multi-question requests when any one condition triggers.
Measure end-to-end latency at the application boundary. Record the primary duration and total duration when the second stage runs, then compare median and tail percentiles. A matched fallback is a second complete decision, so measure the full added stage; the exact delay depends on your models and request path. Also record the proportion of requests that trigger the fallback. That rate is necessary to understand both the latency impact and the second-stage spend.
Since Vercel states that a triggered fallback runs a second decision and bills both stages, estimate added cost from your actual request mix and current model prices. Keep the arithmetic visible: fallback-trigger rate multiplied by the cost of the second decision gives the incremental spend per request on average, before any differences in token usage. Recalculate when traffic mix or model choice changes. Do not infer price from the confidence score or treat a threshold as a cost control by itself.
Choose the threshold by weighing missed errors against unnecessary escalations. Lowering a confidence threshold may send fewer requests to the second model, but it can also leave more low-confidence mistakes untouched. Raising it may catch more uncertain cases while spending more and increasing the time of more requests. Plot those outcomes across candidate thresholds from the evaluation data, then choose a point that meets the product’s error budget and latency target. If there is no threshold where the fallback improves the mistakes that matter at an acceptable cost, leave the condition off.
Roll out with an escape hatch
Start with a narrow question and a small traffic slice. Preserve a way to disable the conditional model entry without changing the primary decision path. Monitor trigger rate, changed-answer rate, correctness signals, latency percentiles, and spend together; a lower error count alone can hide an unacceptable delay or bill. Set alert thresholds from your service objectives and baseline rather than copying the example’s 0.6 value.
Review sampled fallback cases under your data policy. Check whether the second model improves uncertain answers. If it repeats the first answer, changes correct decisions to wrong ones, or triggers where confidence is not calibrated, revise the question or remove the fallback. The mechanism does not validate either model's calibration.
This is distinct from choosing a decision model in the first place. If you are still deciding which structured decision model to use, start with the guide to decision models in AI Gateway. Confidence-based fallback is the follow-up question: after the primary decision model is selected, should a specific uncertain result be run through another model?
Decision fallbacks remain beta. Verify current documentation before upgrading, keep the rollout reversible, and measure on labeled traffic before using the feature for consequential decisions.
Sources
- Vercel AI Gateway: Decision Fallbacks documentation — supported question types, configuration shape, execution behavior, beta status, and two-stage usage.
Buy once, own the code. Ship with the agent you already use.
- Free, open-source SDK — same component, web and mobile
- Paid kits include AI configs + 40+ tested prompts — your agent reads the whole project
- $99/kit or $149 for everything. No subscription, no sandbox limit.