
Drives for Vercel Sandbox: persist the workspace, not the run
Vercel put Drives for Sandbox in public beta on 22 September 2026. The useful part is not a bigger temporary disk. It is a durable volume you create once, mount into a sandbox, and still have after that sandbox is gone.
That split matters if you are running coding agents. A sandbox is a good place to execute a task. It is a bad place to be the system of record for the checkout, the installed dependencies, and the files the agent just wrote. Kill the sandbox and that disk goes with it. The next run starts from an empty tree unless you rebuild it from git, a tarball, or some side store you operate yourself. Drives are the platform's answer to that gap: Drive.getOrCreate, then mount the result when you call Sandbox.create. The agent workspace and its dependencies can survive across runs. The process, the temp files, and the rest of the sandbox disk should not.
This is a different change from the sandbox storage size bump. Capacity and durability solve different failures. A larger ephemeral disk lets one run hold a bigger working set. It does not make the next run cheaper, and it does not give a second sandbox a consistent view of the first sandbox's tree. If you only needed more room inside a single run, the size change is the note to read: Vercel Sandbox's larger disk. If the agent has to resume, or several sandboxes have to look at the same tree without stepping on each other, you need a Drive.
Two places a file can live
Treat the sandbox disk as scratch that belongs to one run. Treat the Drive as the workspace that belongs to the task.
The sandbox disk is where the machine boots, where the process table lives, and where anything you do not mount ends up. It is the right place for files that are only meaningful while that process is alive: sockets, pid files, scratch test output you do not intend to keep, unpacked archives you will throw away, and intermediate build debris you want a clean run to regenerate. When the sandbox stops, that disk is done. That is a feature. You do not want a half-written node_modules, a crashed package-manager lock, or a secret that was written to /tmp to become the next run's starting state by accident.
The Drive is the opposite contract. You get it or create it by a stable name, then you mount it into the sandbox you are about to start. Files written there are still there when you mount the same Drive into a later sandbox. That is the right place for the agent workspace itself: the repo checkout the agent is editing, the notes and patches it has already produced, and the dependency tree you are tired of reinstalling. The point of the beta, for a builder, is that those bytes outlive the sandbox that produced them.
The call sequence
The shape is short, and the order is the whole design.
First, Drive.getOrCreate. The name is the identity. A later run that asks for the same drive should get the volume that already holds the workspace, not a fresh empty one. Create-on-miss is what you want for the first task in a session. Get-if-present is what you want for every resume. One call covers both, which is why agents should not invent their own "does this volume exist" dance in front of it.
Second, mount that drive in Sandbox.create. The sandbox is still ephemeral. You are attaching a durable volume at start, not promoting the sandbox disk into permanent storage. When this sandbox exits, the drive remains. The next Sandbox.create mounts it again and sees the tree the last run left behind.
11 production screens. Login, database, payments — all wired.
The SaaS Dashboard Kit ships everything already connected. Nothing to set up. Live demo at saas.otf-kit.dev.
What belongs on the Drive
Put the agent workspace on the Drive. That means the working tree the agent is allowed to edit, and the files a later step must see without rebuilding them. A checkout that already contains the agent's uncommitted edits is the obvious case. So is a directory of generated patches, review notes, or task state that your harness reads on the next turn. If losing it would force the agent to redo work, it belongs on the drive.
Put installed dependencies on the Drive when they are large relative to the run and stable enough to reuse. A full install at the start of every sandbox is often the slowest honest step in an agent loop, and it has nothing to do with the task. Surviving that install across runs is the practical win next to surviving the source tree. Reinstall when the lockfile changes, not because the sandbox was recycled.
Put caches on the Drive only when you understand what a stale entry does. A package cache that is content-addressed is usually a safe resident. A compiler cache keyed to paths that change between mounts is a way to poison the next run. If you cannot explain the invalidation rule, leave the cache on the ephemeral disk and pay the rebuild.
Leave these on the sandbox disk:
Read-write for the owner, read-only snapshots for everyone else
Mount read-write from the sandbox that is allowed to change the workspace. That is the agent doing the task, or whichever single writer your harness has designated. One writer, one mount, then the sandbox exits. The drive holds the result.
Do not hand that same read-write mount to a pool of siblings. Parallel sandboxes that can all write the workspace will race on the tree, on the dependency directory, and on any lockfile the agent is in the middle of editing. You will not get a faster review. You will get a workspace you can no longer explain.
For parallel review and test, mount read-only snapshots. The writer has finished a step, or you explicitly want other sandboxes to inspect the tree as it stands. Each reviewer or test runner gets a read-only view. They can install nothing into the shared workspace, delete nothing, and commit nothing back. They can still read the source, run tests against that tree, and produce their own reports on their own ephemeral disks.
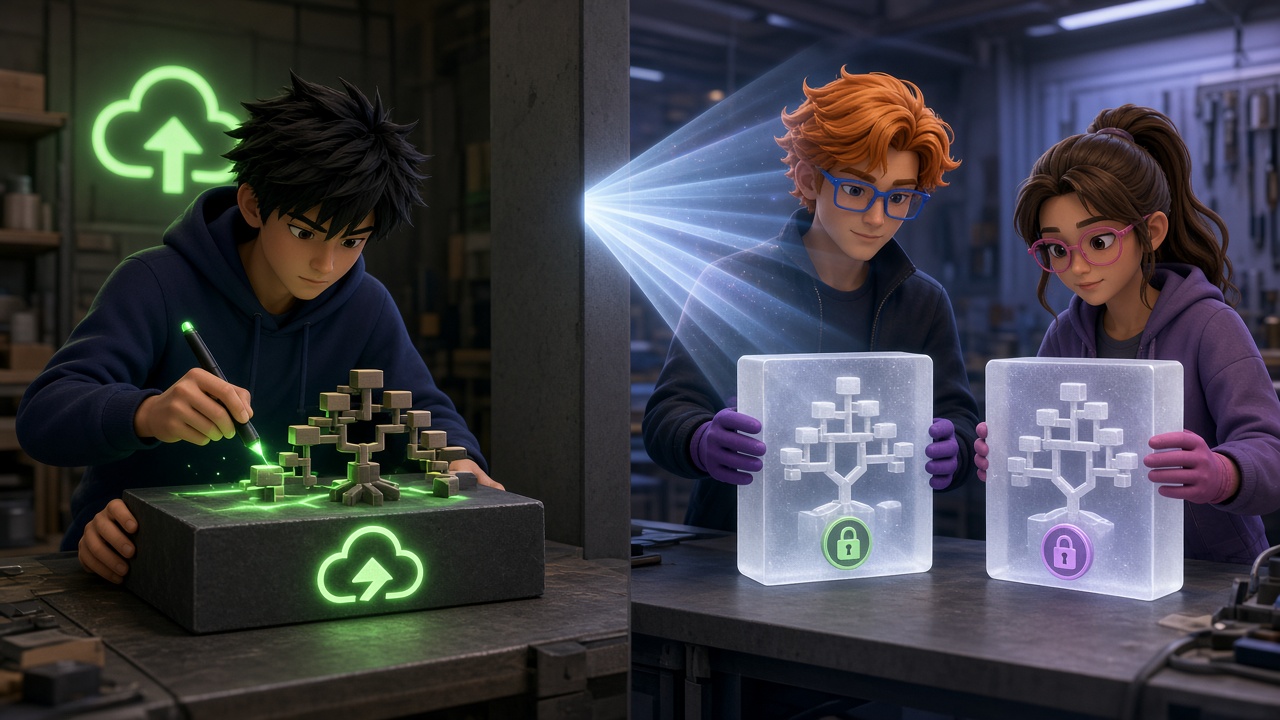
That split is the concurrency model. Read-write is exclusive in intent: one sandbox mutates, then it is done. Read-only snapshots are the fan-out: many sandboxes observe a consistent tree at the same time. The snapshot matters because "read-only" on a live, still-changing volume is a weaker promise. A reviewer that sees half a write is not reviewing the revision you think it is. A snapshot freezes the tree those parallel sandboxes share. The writer can continue on the writable drive afterward without rewriting the reviewers' view under them.
A concrete agent loop
A durable session looks like this.
The harness calls Drive.getOrCreate with the name for this task, branch, or conversation. The first time, the drive is empty and the sandbox clones the repo onto the mount, then installs dependencies there. Later times, the mount already has that tree and those dependencies. The sandbox is new either way. The workspace is not.
The agent runs against the mount. Edits land on the drive. Tool output you care about keeping is written onto the drive. Tool output you do not care about stays on the sandbox disk.
What this does not fix
A drive does not make the sandbox a VM you should babysit for days. The compute is still a run. Persistence is the volume. If your agent needs a process that stays up, a drive does not give you that. It gives the next process the files.
A drive does not replace git. It preserves a working tree, including whatever messy intermediate state the agent left. That is what you want between turns. It is not a history, a review surface, or a backup you can trust outside this platform. Commit when a human or a later system needs a real revision. Do not point at the drive and call it the repository of record.
How this sits next to a larger sandbox disk
Give a run a larger ephemeral disk when the working set inside that run does not fit: a heavy install you are about to throw away, a corpus you only read once, a build that spills. That is a size problem. The earlier storage bump is about that problem, and only that problem.
Give a task a Drive when the next run must see this run's files, or when several sandboxes must share a frozen view. That is a lifetime-and-sharing problem. Buying a bigger scratch disk and calling it memory is the mistake this beta is for. The bytes that justify their cost are the ones you would otherwise recreate on every Sandbox.create: the edited workspace and the dependencies you already installed.
Owned backends still need the same timeout discipline on the harness that mounts drives — see API timeouts and retries for owned AI backends.
Sources
- Drives for Vercel Sandbox are now in public beta — Vercel Changelog (2026-09-22)
Ship the product, not the setup.
- 11 production screens — auth, billing, team, analytics, settings
- Real database, payments, and login — all wired on day 1
- AI configs pre-tuned so your agent extends instead of regenerates