
Circuit breakers on an owned backend: fail fast when the AI vendor fails
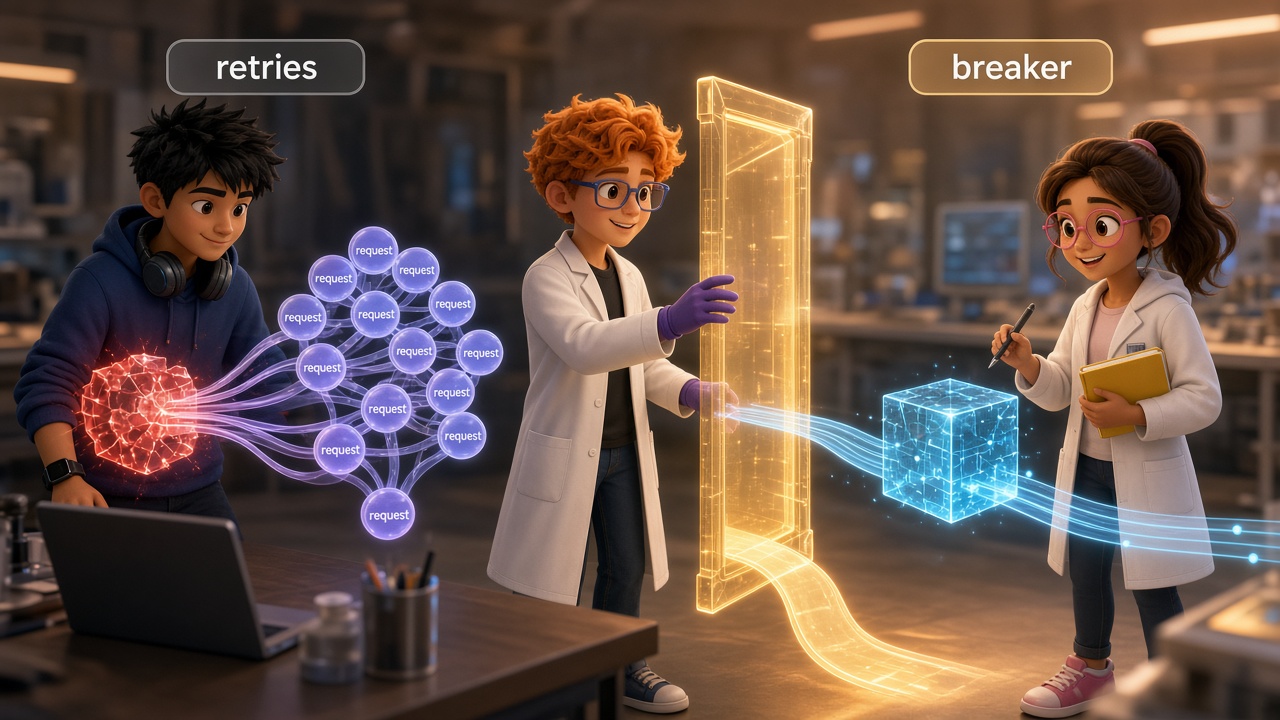
When a downstream AI or vendor HTTP dependency starts failing, the owned API should stop waiting on it. A circuit breaker opens after a measured run of failures and returns a cached, stale, or degraded response immediately. The process stays available. Threads and event-loop slots are not pinned to a vendor that is already down. Retries alone do the opposite: every caller keeps burning the timeout budget and the retry budget, which multiplies load on a dependency that is already sick.
This post is the breaker state machine. Outbound wait and retry live in timeouts and retries for AI backends. Parking work for later is a dead-letter queue concern. The breaker decides whether this dependency may be called right now.
What cascading failure looks like without a breaker
Martin Fowler's circuit breaker note and Microsoft's Azure Architecture Center pattern describe the same operator failure mode. A remote call hangs or errors. Callers retry. Each attempt occupies a worker or a promise until the client timeout fires. The owned API's latency SLO collapses even though its own code is fine, because capacity is stuck on calls that cannot succeed.
AI providers make this sharp: a chat or embeddings call can sit for tens of seconds before a 503, a 429, or a transport error. Retries multiply in-flight work. Health checks that also call the vendor start failing. Autoscaling adds instances that open more connections to the same broken endpoint. A breaker does not fix the vendor. It bounds the blast radius so routes you still own — auth, database reads, previously computed answers — keep returning.
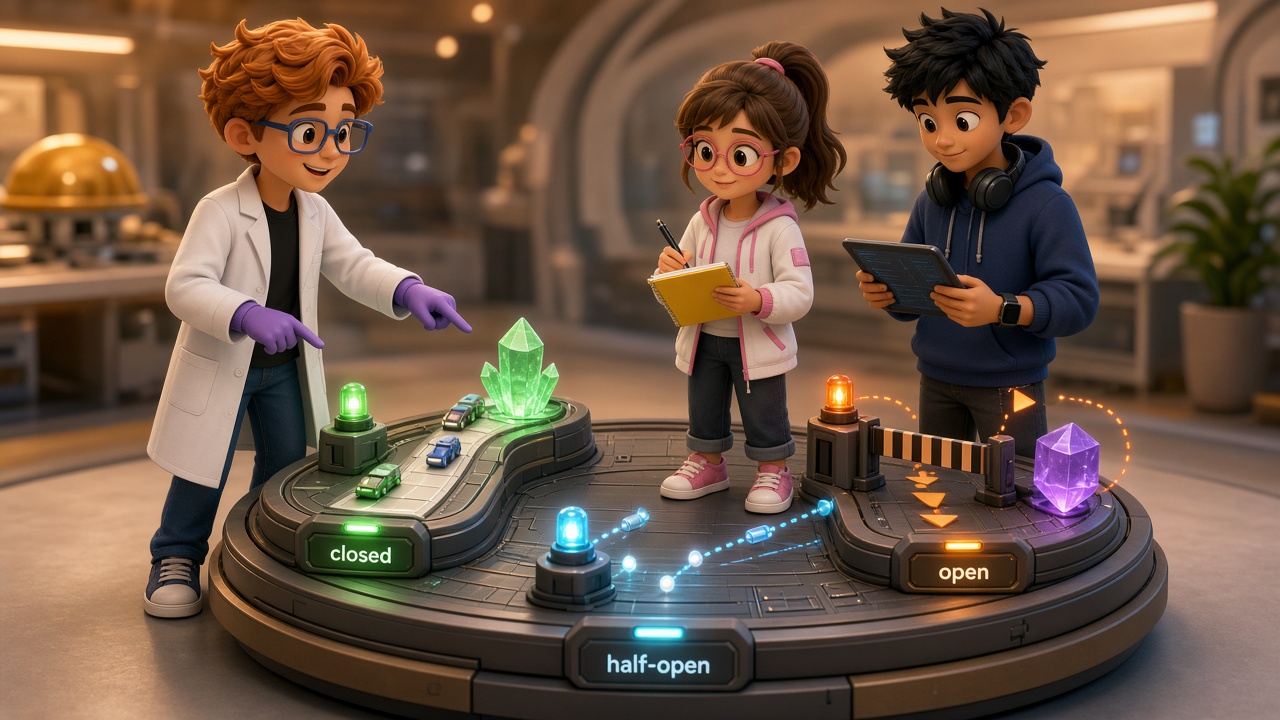
Closed, open, half-open
The state machine used by Azure Architecture Center, AWS Prescriptive Guidance, Resilience4j, and the Node and Go libraries below is the same three states Fowler sketched.
Closed. Calls go through. Outcomes are recorded. Failures count only when they are dependency failures. If the failure rate over the window stays under the threshold, the breaker stays closed.
Open. Calls are not attempted. The owned handler returns the fallback immediately and logs that the call was rejected because the circuit is open. A timer ($CB_WAIT_OPEN_MS) must elapse before any probe is allowed.
Half-open. After the wait, a small number of trial calls ($CB_HALF_OPEN_CALLS) are permitted. Success closes the breaker. Failure opens it again and restarts the wait. Half-open discovers recovery without dumping full QPS onto a vendor that just came back.
While open, the fallback is a product decision: cached completion, last-known embeddings, a static degraded payload, or a 503 with a short Retry-After you control. You do not learn the vendor is still down by waiting for $AI_PROVIDER_BASE_URL to time out again.
11 production screens. Login, database, payments — all wired.
The SaaS Dashboard Kit ships everything already connected. Nothing to set up. Live demo at saas.otf-kit.dev.
Why retries without a breaker amplify load
| Retries only | Breaker plus fallback | |
|---|---|---|
| Vendor 503 storm | Every request waits, then retries | After the threshold, new requests skip the network |
| In-flight work | Grows with concurrency × attempts | Caps at calls already in flight when the breaker opens |
| User latency | Sum of timeouts and backoffs | Fallback latency, typically a cache read |
| Recovery | All callers slam the vendor on the first green blip | Half-open probes, then close |
| 4xx from your bug | Often retried if classified poorly | Ignored by the breaker; you still fix the client |
Azure's pattern page is explicit: a circuit breaker is not a substitute for retry. Retries and timeouts wrap one attempt sequence; if the breaker is open, do not start that sequence. CallNotPermittedException (Resilience4j) and opossum's reject event are the signals to stop.
A DLQ is the wrong tool for this request path — it parks work you already accepted. A user on POST /v1/answer needs fail-fast plus degraded body; background enrichment can use the DLQ separately.
What to count as failure
Resilience4j documents a 50 percent failure-rate threshold, sliding windows, minimumNumberOfCalls, slow-call rate, wait in open state, half-open permits, and recordExceptions / ignoreExceptions.
Count toward the breaker: outbound client timeouts; connection resets, DNS failures, TLS handshake errors; HTTP 5xx; HTTP 429 and 503 treated as dependency health signals.
Do not count: HTTP 4xx that are your bug or bad user input (400, 404, 422); client cancellations; business outcomes you already decided. Opening on 4xx lets a malformed-body deploy take the dependency "down" while the vendor is healthy.
Slow calls deserve a separate rate: a body that always arrives in 28 seconds will not trip failure-rate and will still exhaust your pool. Use Resilience4j's slow-call threshold or opossum's timeout — pick one definition of "too slow."
One breaker per dependency
Do not share one breaker across unrelated providers or shards. A search vendor and a chat vendor fail independently. Key by dependency name: chat-provider, embeddings-provider, not outbound-http. Extra breakers are cheap; a false open on unrelated traffic is not.
Name them in metrics and logs. On transition and reject, log breaker name, new state, correlation id, and route — the same discipline as production structured logging for agents.
Libraries and settings
Prefer a maintained implementation. Resilience4j (JVM): sliding windows, failureRateThreshold default 50, slow-call rate, minimum calls, open wait, half-open permits, CallNotPermittedException, exception filters. opossum (Node): timeout, errorThresholdPercentage, resetTimeout, fallback, plus reject/open/halfOpen/close events. sony/gobreaker (Go): ready-to-trip, open-state timeout, max half-open requests. AWS Prescriptive Guidance and Microsoft Azure Architecture Center describe the same machine without a library.
Read at process start: $CB_FAILURE_RATE_THRESHOLD, $CB_SLIDING_WINDOW, $CB_WAIT_OPEN_MS, $CB_HALF_OPEN_CALLS, and $AI_PROVIDER_BASE_URL. Require a minimum number of calls before evaluating rate — opening on the first failure flaps.
TypeScript sketch for one outbound AI client
The timeout and retry wrapper is the one from the timeouts post. The breaker sits outside it so an open circuit never enters the retry loop.
type AiResult =
  | { ok: true; body: unknown; servedBy: "live" | "cache" }
  | { ok: false; degraded: true; reason: "circuit_open" | "upstream_failed" };

// settings: $CB_FAILURE_RATE_THRESHOLD $CB_SLIDING_WINDOW
// $CB_WAIT_OPEN_MS $CB_HALF_OPEN_CALLS ; URL: $AI_PROVIDER_BASE_URL

async function completeWithBreaker(
  correlationId: string,
  input: { promptHash: string; prompt: string }
): Promise<AiResult> {
  const breaker = breakers.get("chat-provider");

  if (!breaker.tryAcquire()) {
    logger.warn({
      msg: "circuit_rejected",
      breaker: "chat-provider",
      state: breaker.state(),
      correlationId,
    });
    const cached = await cache.get(input.promptHash);
    if (cached) return { ok: true, body: cached, servedBy: "cache" };
    return { ok: false, degraded: true, reason: "circuit_open" };
  }

  try {
    const body = await withTimeoutAndRetry(() =>
      postChat($AI_PROVIDER_BASE_URL, input)
    );
    breaker.recordSuccess();
    await cache.set(input.promptHash, body);
    return { ok: true, body, servedBy: "live" };
  } catch (err) {
    if (isDependencyFailure(err)) breaker.recordFailure();
    else breaker.recordSuccess(); // 4xx business: not vendor health
    const cached = await cache.get(input.promptHash);
    if (cached) return { ok: true, body: cached, servedBy: "cache" };
    return { ok: false, degraded: true, reason: "upstream_failed" };
  }
}
tryAcquire returns false when open or when half-open already has $CB_HALF_OPEN_CALLS in flight. Count timeouts, connection errors, 429, 503, and other 5xx as failures; ignore 4xx for the window. Invoke withTimeoutAndRetry only after acquire succeeds.
Checklist for the owned API
- One breaker per independent dependency, named in logs and metrics.
- Record failures for timeouts, connection errors, 5xx, and vendor 429/503.
- Ignore 4xx that indicate a bad request rather than a bad dependency.
- Evaluate failure rate only after a minimum number of calls in
$CB_SLIDING_WINDOW. - Open when the rate exceeds
$CB_FAILURE_RATE_THRESHOLD. - While open, skip
$AI_PROVIDER_BASE_URL; return cache or degraded body; log breaker name, state, correlation id. - After
$CB_WAIT_OPEN_MS, allow$CB_HALF_OPEN_CALLSprobes; close on success, re-open on failure. - Emit metrics on every transition and reject.
- Keep timeouts and a small retry budget for the closed state. Stop retrying when the call is not permitted.
- Do not use the breaker as a DLQ, and do not use a DLQ as a live fail-fast.
How this sits next to the other controls
Timeouts cap one call. Retries spend a fixed budget on transient faults. The breaker removes the dependency from the hot path after that budget is clearly wasted. Rate limiting protects you from your callers; it does not protect you from a vendor that accepts the connection and then stalls. Background jobs that call the same vendor should use a sibling breaker with a looser threshold so batch volume does not open the circuit for interactive traffic — when retries are spent and the breaker is open, park the job in the DLQ.
While open, return a cache hit marked servedBy: "cache", a stale-but-bounded row, a stable degraded JSON object with your correlation id, or a null optional enrichment while the primary database read still returns. Do not fall through an open breaker into an unbounded call to a second vendor — give the backup its own breaker.
If you own the repo, put the breaker next to the HTTP client that already holds timeouts and structured log fields. OTF's owned-repo kits are built around that client boundary; add the breaker in the same module instead of inventing a second outbound stack.
The vendor will fail again. The owned API should notice quickly, stop calling, serve the fallback, and try a few probes later. That is the whole machine.
Sources
- Martin Fowler, CircuitBreaker: https://martinfowler.com/bliki/CircuitBreaker.html
- Microsoft Azure Architecture Center, Circuit Breaker pattern: https://learn.microsoft.com/en-us/azure/architecture/patterns/circuit-breaker
- Resilience4j CircuitBreaker: https://resilience4j.readme.io/docs/circuitbreaker
- AWS Prescriptive Guidance, Circuit breaker pattern: https://docs.aws.amazon.com/prescriptive-guidance/latest/cloud-design-patterns/circuit-breaker.html
- opossum (Node): https://www.npmjs.com/package/opossum
- sony/gobreaker (Go): https://github.com/sony/gobreaker
- Related: https://otf-kit.dev/blog/api-timeouts-retries-ai-backends
- Related: https://otf-kit.dev/blog/dead-letter-queue-background-jobs
- Related: https://otf-kit.dev/blog/production-structured-logging-for-agents
Ship the product, not the setup.
- 11 production screens — auth, billing, team, analytics, settings
- Real database, payments, and login — all wired on day 1
- AI configs pre-tuned so your agent extends instead of regenerates